
Ver5.0 🧮 파이썬으로 토큰 길이 자동 계산기 개발하기: tiktoken부터 비용 추정·청크 분할까지
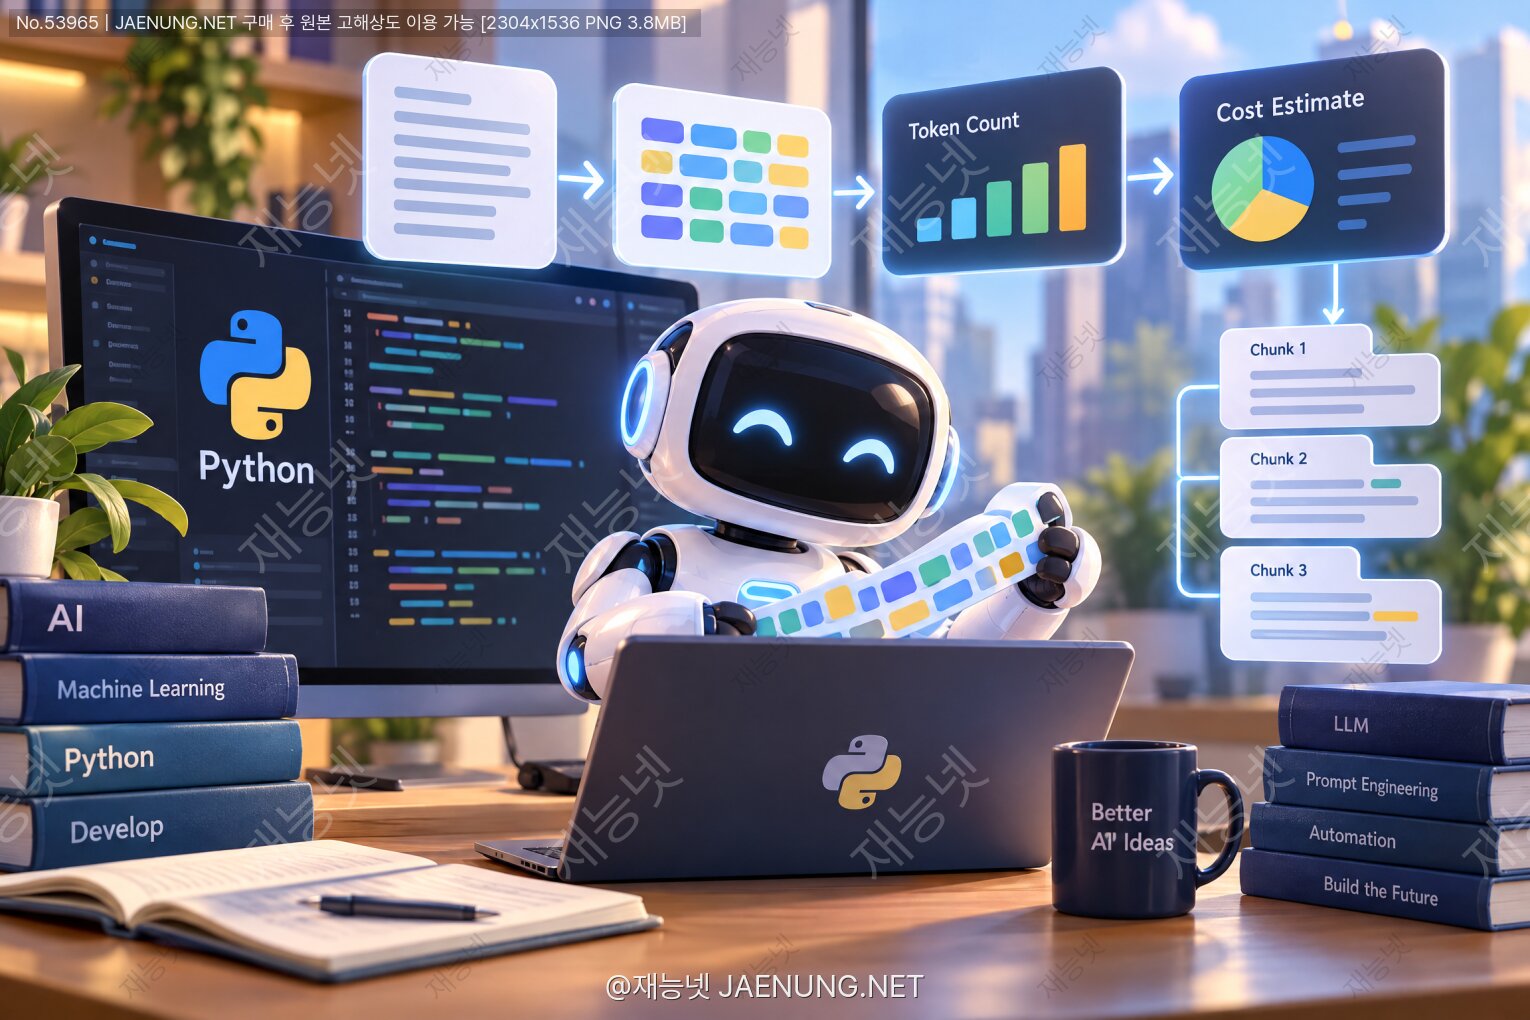
🧮 파이썬으로 토큰 길이 자동 계산기 개발하기: tiktoken부터 비용 추정·청크 분할까지
"글자 수 3,000자면 몇 토큰이야?" 이 질문에 매번 감으로 대답하고 있었다면, 오늘 그 감을 코드로 바꿔봅시다. 파이썬 몇십 줄로 시작해서 실전에서 쓸 수 있는 토큰 계산기까지 같이 만들어 볼게요. 🍵
※ 그림 속 토큰 ID는 설명용 예시예요. 실제 값은 인코딩마다 다릅니다.
1. 왜 하필 "토큰"을 세야 할까? 🤔
LLM(대규모 언어 모델)은 우리가 보내는 글을 글자 단위로 읽지 않아요. 먼저 토크나이저가 문장을 잘게 쪼개 정수 ID 배열로 바꾸고, 모델은 그 숫자 배열을 처리합니다. 그래서 API 요금, 컨텍스트 윈도우(한 번에 넣을 수 있는 길이), 출력 길이 제한이 전부 글자 수가 아니라 토큰 수 기준으로 정해져 있어요.
문제는 "글자 수 ÷ 몇" 같은 어림셈이 언어마다, 모델마다, 심지어 같은 모델의 버전마다 다르게 틀린다는 점이에요. 영어 문장은 대체로 단어 하나가 토큰 한두 개로 끝나지만, 한국어는 같은 의미를 표현할 때 토큰이 더 많이 나오는 경향이 있고, 코드·URL·이모지는 또 다른 패턴을 보입니다. 결국 정확한 값이 필요하면 해당 모델의 토크나이저로 직접 세는 게 유일한 정답이에요.
2. 토크나이저는 문장을 어떻게 자를까? (BPE 한 입 맛보기) 🍰
요즘 GPT 계열을 비롯한 많은 모델이 쓰는 방식은 BPE(Byte Pair Encoding) 계열이에요. 원리는 생각보다 단순합니다.
여기서 중요한 포인트! 병합 규칙은 학습 데이터의 빈도로 만들어지기 때문에, 학습 데이터에 많이 등장한 언어·패턴일수록 큰 덩어리로 묶여 토큰이 적게 나와요. 영어가 상대적으로 "토큰 효율"이 좋은 이유가 이거예요. 한국어는 한 음절이 UTF-8로 3바이트를 차지하고, 바이트 수준 BPE에서는 자주 쓰이지 않는 음절이 여러 바이트 토큰으로 쪼개질 수 있어서 토큰 수가 늘어나기 쉽습니다.
다른 방식도 있어요. Google 계열과 여러 오픈 모델에서 쓰여 온 SentencePiece(BPE 또는 Unigram 알고리즘 지원), BERT 계열의 WordPiece 등이죠. 알고리즘이 달라도 계산기 입장에서 할 일은 똑같아요. "해당 모델의 토크나이저를 불러와서 encode한 뒤 길이를 잰다." 끝!
3. 어떤 라이브러리로 셀까? 도구 지도 🗺️
"어떤 모델의 토큰을 세고 싶은가"에 따라 도구가 갈려요. 표로 정리해 볼게요.
| 대상 모델 | 추천 방법 | 특징 |
|---|---|---|
| OpenAI GPT 계열 | tiktoken (pip install tiktoken) | OpenAI가 공개한 빠른 BPE 토크나이저. 로컬에서 오프라인 계산 가능(최초 1회 인코딩 파일 다운로드) |
| Hugging Face 공개 모델 (Llama, Mistral, Qwen, Gemma 등) | transformers의 AutoTokenizer | 모델 저장소의 tokenizer 파일을 그대로 사용. 일부 모델은 접근 승인 필요 |
| Anthropic Claude | 공식 SDK의 토큰 카운팅 API | 메시지·시스템 프롬프트·도구 정의를 포함한 입력 토큰 수를 서버가 계산해 줌 |
| Google Gemini | 공식 SDK의 count_tokens | 서버 측 계산. 텍스트 외 멀티모달 입력도 집계 |
4. 가장 작은 토큰 계산기: 10줄로 시작하기 ⚡
먼저 설치부터 해요.
pip install tiktoken그리고 대망의 첫 코드입니다.
import tiktoken

enc = tiktoken.get_encoding("o200k_base")   # GPT-4o 계열에서 쓰는 인코딩
text = "안녕하세요! 토큰 계산기를 만들어 봅시다."
tokens = enc.encode(text)

print("토큰 수:", len(tokens))
print("토큰 ID:", tokens)
print("복원:", enc.decode(tokens))
이게 전부예요. encode()가 정수 리스트를 돌려주고, 그 len()이 토큰 수예요. decode()로 다시 원문이 복원되는지도 확인할 수 있죠.
인코딩 이름 vs 모델 이름
tiktoken은 두 가지 방식으로 인코더를 불러요.
enc_a = tiktoken.get_encoding("cl100k_base")      # 인코딩 이름으로
enc_b = tiktoken.encoding_for_model("gpt-4o")     # 모델 이름으로
print(enc_b.name)   # o200k_base
대표적인 매핑은 이래요. GPT-4·GPT-3.5-turbo 및 text-embedding-3 계열 임베딩 모델은 cl100k_base, GPT-4o 계열은 o200k_base, 그보다 오래된 GPT-3 계열은 r50k_base·p50k_base를 사용했어요. 이름의 숫자처럼 cl100k_base는 약 10만 개, o200k_base는 약 20만 개 규모의 어휘를 갖고 있고, 어휘가 커지면서 영어 이외 언어의 토큰 효율이 개선되었다고 알려져 있어요.
encoding_for_model()은 tiktoken이 모르는 모델명을 넣으면 KeyError를 던져요. 새 모델이 나오면 라이브러리 업데이트 전까지 이런 일이 생기니, 계산기에는 기본 인코딩으로 떨어지는 폴백을 꼭 넣어 두세요. (아래 실전 코드에 들어 있어요.)함정 하나: 특수 토큰 에러
사용자가 붙여 넣은 텍스트에 <|endoftext|> 같은 문자열이 들어 있으면 tiktoken의 encode()는 기본적으로 ValueError를 일으켜요. 특수 토큰이 의도치 않게 주입되는 걸 막는 안전장치거든요. 계산기에서는 이렇게 처리하면 됩니다.
# 특수 토큰 문자열도 그냥 "일반 텍스트"로 취급해서 셈
n = len(enc.encode(text, disallowed_special=()))

# 또는 특수 토큰 처리를 아예 하지 않는 함수
n = len(enc.encode_ordinary(text))
로그 파일이나 크롤링 데이터처럼 "무엇이 들어올지 모르는" 입력을 다루는 계산기라면 이 처리가 사실상 필수예요. 이거 안 하면 새벽에 배치 돌리다 터지는 경험을 하게 됩니다. 😇
5. 채팅 메시지는 본문만 세면 손해 본다 💬
Chat Completions처럼 messages 배열을 보내는 API는 각 메시지에 역할(role) 구분용 포맷 토큰이 붙어요. 그래서 메시지 내용만 합친 토큰 수보다 실제 청구 토큰이 조금 더 많습니다. OpenAI Cookbook의 "How to count tokens with tiktoken" 예제에서는 gpt-3.5-turbo·gpt-4 계열 기준으로 메시지마다 3토큰, name 필드가 있으면 1토큰 추가, 그리고 응답 시작용으로 3토큰을 더하는 방식으로 계산해요.
def count_chat_tokens(messages, model="gpt-4o"):
    """OpenAI Cookbook 방식의 근사 계산.
    모델에 따라 오버헤드가 달라질 수 있으므로 '추정치'로 사용."""
    try:
        enc = tiktoken.encoding_for_model(model)
    except KeyError:
        enc = tiktoken.get_encoding("o200k_base")

    tokens_per_message = 3
    tokens_per_name = 1
    total = 0
    for msg in messages:
        total += tokens_per_message
        for key, value in msg.items():
            total += len(enc.encode(str(value), disallowed_special=()))
            if key == "name":
                total += tokens_per_name
    total += 3  # 어시스턴트 응답 프라이밍
    return total

msgs = [
    {"role": "system", "content": "너는 친절한 파이썬 튜터야."},
    {"role": "user", "content": "리스트 컴프리헨션 설명해줘"},
]
print(count_chat_tokens(msgs))usage 필드입니다. 계산기는 "사전 추정", usage는 "사후 정산"이라고 생각하면 깔끔해요.6. 다른 모델 패밀리도 세어 보자 🌐
Hugging Face 오픈 모델
from transformers import AutoTokenizer

tok = AutoTokenizer.from_pretrained("Qwen/Qwen2.5-7B-Instruct")
text = "오픈 모델의 토큰 수를 세어 봅니다."

ids = tok.encode(text, add_special_tokens=False)
print(len(ids))

# 채팅 템플릿까지 포함한 '실제 입력' 길이
messages = [{"role": "user", "content": text}]
chat_ids = tok.apply_chat_template(messages, add_generation_prompt=True)
print(len(chat_ids))
여기서 핵심은 두 가지예요. 첫째, add_special_tokens 기본값에 따라 BOS 같은 특수 토큰이 붙어 숫자가 1~2개 달라질 수 있어요. 둘째, 채팅 모델은 apply_chat_template으로 만든 포맷이 실제 모델 입력이므로, 컨텍스트 한도 검사는 이 값으로 해야 정확합니다. 모델 가중치는 필요 없고 토크나이저 파일만 내려받으니 생각보다 가벼워요. (일부 모델은 허브에서 이용 약관 동의 후 토큰 인증이 필요해요.)
Anthropic Claude
Claude는 로컬 토크나이저 대신 공식 토큰 카운팅 API를 제공해요. 메시지, 시스템 프롬프트, 도구 정의까지 넣어 보내면 입력 토큰 수를 돌려줍니다.
import anthropic

client = anthropic.Anthropic()  # 환경변수 ANTHROPIC_API_KEY 사용
resp = client.messages.count_tokens(
    model="claude-sonnet-4-5",   # 사용 중인 모델 ID로 바꾸세요
    system="너는 코드 리뷰어야.",
    messages=[{"role": "user", "content": "이 함수 리뷰해줘: def f(x): return x*2"}],
)
print(resp.input_tokens)
Google Gemini
from google import genai

client = genai.Client()  # 환경변수 GEMINI_API_KEY 사용
resp = client.models.count_tokens(
    model="gemini-2.0-flash",   # 사용 중인 모델 ID로 바꾸세요
    contents="토큰을 세어 주세요.",
)
print(resp.total_tokens)7. 설계도 그리기: 쓸모 있는 계산기의 구조 🏗️
이제 장난감을 도구로 키워 봅시다. 실제로 쓸 만한 계산기는 보통 이런 기능이 필요해요.
count(text) → int)로 감싸기8. 실전 코드: 백엔드 추상화부터 🧱
하나씩 쌓아 볼게요. 먼저 "무엇으로 세든 같은 모양"으로 쓰기 위한 추상 클래스예요. 파일 이름은 tokcalc.py로 하겠습니다.
from __future__ import annotations
from abc import ABC, abstractmethod
from functools import lru_cache
import tiktoken


class TokenCounter(ABC):
    name: str = "base"
    exact: bool = True   # 대상 모델 기준으로 정확한 값인가?

    @abstractmethod
    def count(self, text: str) -> int: ...

    def count_many(self, texts: list[str]) -> list[int]:
        return [self.count(t) for t in texts]


@lru_cache(maxsize=None)
def _get_encoding(name: str):
    # 인코더 로딩은 비싸므로 한 번만
    return tiktoken.get_encoding(name)


class TiktokenCounter(TokenCounter):
    def __init__(self, model: str | None = None, encoding: str | None = None,
                 fallback: str = "o200k_base"):
        if encoding:
            self.enc = _get_encoding(encoding)
        else:
            try:
                self.enc = tiktoken.encoding_for_model(model or "gpt-4o")
            except KeyError:
                self.enc = _get_encoding(fallback)
                self.exact = False      # 모르는 모델 → 추정치
        self.name = f"tiktoken:{self.enc.name}"

    def count(self, text: str) -> int:
        return len(self.enc.encode(text, disallowed_special=()))

    def count_many(self, texts: list[str]) -> list[int]:
        # 내부적으로 스레드를 써서 여러 텍스트를 한 번에 인코딩
        batches = self.enc.encode_batch(texts, disallowed_special=())
        return [len(b) for b in batches]

    def encode(self, text: str) -> list[int]:
        return self.enc.encode(text, disallowed_special=())

    def decode(self, ids: list[int]) -> str:
        return self.enc.decode(ids)


class HFCounter(TokenCounter):
    def __init__(self, repo_id: str):
        from transformers import AutoTokenizer   # 필요할 때만 임포트
        self.tok = AutoTokenizer.from_pretrained(repo_id)
        self.name = f"hf:{repo_id}"

    def count(self, text: str) -> int:
        return len(self.tok.encode(text, add_special_tokens=False))

    def encode(self, text: str) -> list[int]:
        return self.tok.encode(text, add_special_tokens=False)

    def decode(self, ids: list[int]) -> str:
        return self.tok.decode(ids)


def make_counter(model: str) -> TokenCounter:
    """'hf:저장소ID' 형식이면 HF, 아니면 tiktoken."""
    if model.startswith("hf:"):
        return HFCounter(model[3:])
    return TiktokenCounter(model=model)
포인트를 짚어 보면요.
👉 lru_cache로 인코더 캐싱: tiktoken 인코더는 처음 로드할 때 어휘 파일을 읽고(최초엔 다운로드까지) 내부 자료구조를 만들어요. 파일 1,000개를 셀 때마다 새로 만들면 시간 낭비죠.
👉 exact 플래그: 폴백으로 떨어졌다면 사용자에게 "이건 추정치예요"라고 정직하게 알려 주기 위한 장치예요. 이런 디테일이 도구의 신뢰도를 만듭니다.
👉 지연 임포트: transformers는 무거운 패키지라 HF 백엔드를 쓸 때만 불러와요. CLI 시작 속도가 확 달라집니다.
TIKTOKEN_CACHE_DIR로 위치를 지정하는 방식이 흔히 쓰여요.9. 파일·폴더 일괄 계산과 리포트 📂
이제 진짜 "자동" 계산기다운 부분이에요. 폴더를 통째로 넣으면 파일별 토큰 수를 쫙 뽑아 주는 기능입니다.
from dataclasses import dataclass
from pathlib import Path

TEXT_EXTS = {".txt", ".md", ".py", ".json", ".csv", ".html", ".js", ".ts", ".yaml", ".yml"}


@dataclass
class FileStat:
    path: str
    chars: int
    tokens: int

    @property
    def tokens_per_char(self) -> float:
        return self.tokens / self.chars if self.chars else 0.0


def read_text(path: Path) -> str | None:
    for encoding in ("utf-8", "cp949"):     # 국내 레거시 파일 대비
        try:
            return path.read_text(encoding=encoding)
        except UnicodeDecodeError:
            continue
    return None   # 바이너리 등은 건너뜀


def iter_files(target: Path):
    if target.is_file():
        yield target
        return
    for p in sorted(target.rglob("*")):
        if p.is_file() and p.suffix.lower() in TEXT_EXTS:
            yield p


def scan(target: Path, counter: TokenCounter) -> list[FileStat]:
    paths, texts = [], []
    for p in iter_files(target):
        t = read_text(p)
        if t is not None:
            paths.append(p)
            texts.append(t)
    counts = counter.count_many(texts)
    return [FileStat(str(p), len(t), n) for p, t, n in zip(paths, texts, counts)]
cp949 폴백은 한국 개발자라면 공감할 디테일이에요. 오래된 윈도우 환경에서 만든 메모장 파일은 UTF-8이 아닌 경우가 꽤 있거든요. 글자 수(chars)도 같이 저장해 두면 "글자당 토큰 비율"을 볼 수 있어서, 우리 데이터가 어떤 특성인지 감 잡는 데 아주 좋아요.
10. 비용 추정: 단가는 코드에 박지 말자 💰
요금은 모델마다 다르고, 입력·출력 단가가 따로이며, 캐시 할인·배치 할인 같은 옵션도 있고, 무엇보다 자주 바뀝니다. 그래서 단가는 별도 JSON 파일로 빼는 게 정석이에요.
# prices.json 예시 — 숫자는 형식 설명용 자리표시자입니다.
# 반드시 각 사 공식 가격 페이지의 최신 값을 넣으세요.
{
  "gpt-4o":      {"input_per_1m": 0.0, "output_per_1m": 0.0},
  "my-local-llm":{"input_per_1m": 0.0, "output_per_1m": 0.0}
}
import json
def estimate_cost(model: str, input_tokens: int, expected_output_tokens: int,
price_file: str = "prices.json") -> float | None:
with open(price_file, encoding="utf-8") as f:
prices = json.load(f)
p = prices.get(model)
if p is None:
return None
return (input_tokens * p["input_per_1m"]
+ expected_output_tokens * p["output_per_1m"]) / 1_000_000여기서 많이들 놓치는 게 출력 토큰이에요. 입력은 미리 정확히 셀 수 있지만 출력은 모델이 얼마나 길게 답할지 모르잖아요. 그래서 실무에서는 보통 세 가지 방법 중 하나를 써요.
max_tokens 설정값을 그대로 출력량으로 가정 → 최악의 비용11. 토큰 기준 청크 분할기 ✂️
RAG(검색 증강 생성) 파이프라인을 만들 때 계산기의 진가가 드러나요. 문서를 "최대 N토큰, 앞뒤 M토큰 겹침"으로 자르는 기능이죠.
def chunk_by_tokens(text: str, counter, max_tokens: int = 500,
                    overlap: int = 50) -> list[str]:
    if overlap >= max_tokens:
        raise ValueError("overlap은 max_tokens보다 작아야 합니다.")
    ids = counter.encode(text)
    step = max_tokens - overlap
    chunks = []
    for start in range(0, len(ids), step):
        piece = ids[start:start + max_tokens]
        chunks.append(counter.decode(piece))
        if start + max_tokens >= len(ids):
            break
    return chunks
간단하죠? 그런데 이 순진한 버전에는 한국어 사용자에게 치명적인 함정이 있어요. 앞서 말했듯 바이트 수준 BPE에서는 한글 한 글자가 여러 토큰에 걸쳐 있을 수 있어요. 청크 경계가 하필 그 중간에 떨어지면 decode() 결과 끝에 깨진 문자(�)가 생깁니다.
② 더 좋은 방법: 먼저 문단·문장 단위로 나눈 뒤, 토큰 수를 세면서 한도까지 이어 붙이기. 의미 단위가 보존돼 검색 품질도 좋아져요.
import re

def chunk_by_sentences(text: str, counter, max_tokens: int = 500) -> list[str]:
    # 마침표·물음표·느낌표·줄바꿈 기준의 단순 문장 분리
    sentences = [s for s in re.split(r"(?<=[.!?。])\s+|\n+", text) if s.strip()]
    chunks, buf, buf_tokens = [], [], 0
    for s in sentences:
        n = counter.count(s)
        if n > max_tokens:                       # 한 문장이 너무 길면 토큰 단위로 강제 분할
            if buf:
                chunks.append(" ".join(buf)); buf, buf_tokens = [], 0
            chunks.extend(chunk_by_tokens(s, counter, max_tokens, overlap=0))
            continue
        if buf_tokens + n > max_tokens:
            chunks.append(" ".join(buf)); buf, buf_tokens = [], 0
        buf.append(s); buf_tokens += n
    if buf:
        chunks.append(" ".join(buf))
return chunks12. 명령줄 도구(CLI)로 묶기 🖥️
이제 터미널에서
python tokcalc.py ./docs --model gpt-4o --limit 128000argparse만으로 충분해요.
import argparse
import sys

def main(argv=None):
    ap = argparse.ArgumentParser(description="파이썬 토큰 길이 자동 계산기")
    ap.add_argument("target", nargs="?", help="파일/폴더 경로 (생략 시 표준입력)")
    ap.add_argument("--model", default="gpt-4o",
                    help="모델명 또는 'hf:저장소ID'")
    ap.add_argument("--limit", type=int, default=None,
                    help="컨텍스트 한도(토큰). 초과 파일 경고")
    ap.add_argument("--top", type=int, default=20, help="상위 N개 파일만 출력")
    ap.add_argument("--csv", help="결과를 CSV로 저장할 경로")
    args = ap.parse_args(argv)

    counter = make_counter(args.model)
    if not getattr(counter, "exact", True):
        print(f"⚠️  '{args.model}'을 모릅니다. {counter.name}로 추정합니다.",
              file=sys.stderr)

    if args.target is None:                      # 파이프 입력: cat a.txt | python tokcalc.py
        text = sys.stdin.read()
        print(counter.count(text))
        return 0

    stats = scan(Path(args.target), counter)
    stats.sort(key=lambda s: s.tokens, reverse=True)
    total = sum(s.tokens for s in stats)

    print(f"백엔드: {counter.name} | 파일 {len(stats)}개 | 총 {total:,} 토큰\n")
    for s in stats[:args.top]:
        flag = ""
        if args.limit and s.tokens > args.limit:
            flag = "  🚨 한도 초과"
        print(f"{s.tokens:>10,}  {s.tokens_per_char:5.2f}/자  {s.path}{flag}")

    if args.csv:
        import csv
        with open(args.csv, "w", newline="", encoding="utf-8-sig") as f:
            w = csv.writer(f)
            w.writerow(["path", "chars", "tokens", "tokens_per_char"])
            for s in stats:
                w.writerow([s.path, s.chars, s.tokens, f"{s.tokens_per_char:.4f}"])
    return 0

if __name__ == "__main__":
    raise SystemExit(main())
CSV 저장 시 utf-8-sig를 쓴 이유는 엑셀에서 한글이 깨지지 않게 하려는 거예요(BOM 포함). 이런 사소한 배려가 동료들한테 "오, 이거 잘 만들었네" 소리를 듣게 해줍니다. 😎
sys.stderr로 내보내면, 결과값만 다른 명령어로 파이프할 때 경고 문구가 섞이지 않아요. 예: cat prompt.txt | python tokcalc.py > count.txt13. 화면이 있는 계산기: Streamlit으로 5분 웹앱 🌈
비개발자 동료(기획자, 마케터)도 쓰게 하려면 웹 UI가 최고예요. Streamlit을 쓰면 정말 금방 만들어집니다.
# app.py — 실행: streamlit run app.py
import streamlit as st
from tokcalc import make_counter

st.title("🧮 토큰 길이 계산기")
model = st.selectbox("모델", ["gpt-4o", "gpt-4", "hf:Qwen/Qwen2.5-7B-Instruct"])
limit = st.number_input("컨텍스트 한도(토큰)", value=128000, step=1000)
text = st.text_area("텍스트를 붙여 넣으세요", height=250)

@st.cache_resource
def get_counter(m):
    return make_counter(m)

if text:
    counter = get_counter(model)
    ids = counter.encode(text)
    n = len(ids)
    col1, col2, col3 = st.columns(3)
    col1.metric("토큰 수", f"{n:,}")
    col2.metric("글자 수", f"{len(text):,}")
    col3.metric("한도 사용률", f"{n / limit:.1%}")
    st.progress(min(n / limit, 1.0))

    with st.expander("토큰 쪼개진 모양 보기 (앞 200개)"):
        pieces = [counter.decode([i]) for i in ids[:200]]
st.write(" | ".join(repr(p) for p in pieces))st.cache_resource는 토크나이저 같은 무거운 객체를 세션 간에 재사용하게 해 줘요. 마지막 "쪼개진 모양 보기"에서 토큰을 하나씩 디코딩하면, 앞에서 말한 대로 한글 글자가 바이트 조각으로 나뉜 경우 �처럼 보일 수 있어요. 버그가 아니라 바이트 수준 BPE의 정상 동작이니 놀라지 마세요! tiktoken에는 토큰별 원본 바이트를 돌려주는 decode_single_token_bytes()도 있어서, 바이트 단위로 시각화하고 싶을 때 쓸 수 있어요.
이렇게 만든 도구는 팀 내부 위키에 링크만 걸어 둬도 반응이 좋아요. 프롬프트 엔지니어링이나 AI 자동화 작업을 외주로 주고받는 일이 늘면서, 재능넷 같은 재능 거래 플랫폼에서도 "프롬프트 최적화", "RAG 구축" 같은 의뢰를 할 때 토큰 예산을 수치로 제시하면 견적 소통이 훨씬 명확해집니다.
14. 성능 이야기: 대용량을 빠르게 🚀
몇 개 파일이면 뭐든 빠르지만, 수 GB 로그나 수십만 개 문서라면 이야기가 달라져요.
| 기법 | 설명 | 언제 쓰나 |
|---|---|---|
| 인코더 캐싱 | get_encoding 결과 재사용 (tiktoken 내부에도 캐시가 있지만 명시적으로 관리하면 깔끔) | 항상 |
encode_batch | 여러 텍스트를 스레드로 병렬 인코딩 | 짧은 텍스트 다수 |
| HF Fast 토크나이저 | Rust로 구현된 tokenizers 기반. 리스트를 한 번에 넣으면 배치 처리 | HF 모델 대량 처리 |
| 멀티프로세싱 | concurrent.futures.ProcessPoolExecutor로 파일 단위 분산 | 파일 수가 아주 많을 때 |
| 줄 단위 스트리밍 | 거대한 파일을 통째로 메모리에 올리지 않고 줄·블록 단위로 세서 합산 | 메모리 제한 환경 (약간의 오차 허용) |
def count_large_file(path: Path, counter, block_lines: int = 2000) -> int:
    """거대 파일을 블록 단위로 세서 합산. 블록 경계에서 미세한 오차 가능."""
    total, buf = 0, []
    with path.open(encoding="utf-8", errors="replace") as f:
        for line in f:
            buf.append(line)
            if len(buf) >= block_lines:
                total += counter.count("".join(buf)); buf.clear()
    if buf:
        total += counter.count("".join(buf))
return totalcProfile이나 time.perf_counter()로 직접 재 보는 게 정답이에요. 파일 I/O가 병목인 경우도 많거든요.15. 테스트로 계산기를 믿을 수 있게 ✅
숫자를 내놓는 도구는 틀리면 신뢰를 잃어요. pytest로 핵심 성질을 검증해 둡시다. 특정 토큰 수를 하드코딩하기보다 "성질(property)"을 검사하는 게 라이브러리 버전 변화에도 튼튼해요.
# test_tokcalc.py
import pytest
from tokcalc import TiktokenCounter, chunk_by_tokens, chunk_by_sentences

@pytest.fixture(scope="module")
def counter():
    return TiktokenCounter(encoding="o200k_base")

def test_empty_is_zero(counter):
    assert counter.count("") == 0

def test_roundtrip(counter):
    text = "토큰 계산기 테스트 🧪 with English & code: print('hi')"
    assert counter.decode(counter.encode(text)) == text

def test_special_token_text_does_not_crash(counter):
    assert counter.count("본문 <|endoftext|> 끝") > 0

def test_batch_equals_single(counter):
    texts = ["가나다", "hello world", "x = 1\n"]
    assert counter.count_many(texts) == [counter.count(t) for t in texts]

def test_chunks_respect_limit(counter):
    text = "문장입니다. " * 500
    for c in chunk_by_sentences(text, counter, max_tokens=100):
        assert counter.count(c) <= 110   # 재결합 오차 여유

def test_unknown_model_falls_back():
    c = TiktokenCounter(model="totally-unknown-model")
    assert c.exact is False
특히 test_special_token_text_does_not_crash는 앞에서 말한 특수 토큰 함정이 다시 생기지 않게 막아 주는 "회귀 방지 테스트"예요. 한 번 겪은 버그는 테스트로 박제해 두는 게 개발자의 생존 전략입니다. 🧷
16. 한국어 토큰을 줄이는 실전 감각 🇰🇷
계산기를 만들었으면 이제 그걸로 실험을 해 볼 차례예요. 숫자를 재 보면 의외의 사실들이 보입니다. 아래는 계산기로 직접 비교해 보길 권하는 실험 목록이에요.
측정하지 않으면 개선할 수 없다. 토큰도 마찬가지다. 감으로 프롬프트를 깎지 말고, 계산기로 재고 깎자.
17. 프로젝트 마무리: 배포 형태 고르기 📦
tokcalc.py 하나를 팀 저장소에 두고 공유. 가장 빠르고 단순해요.pyproject.toml에 [project.scripts] 항목으로 tokcalc = "tokcalc:main"을 등록하면 pip install 후 어디서든 tokcalc 명령으로 실행돼요.마지막 "미들웨어" 패턴은 챗봇에서 특히 유용해요. 대화가 길어지면 오래된 메시지부터 빼면서 한도 안에 맞추는 거죠.
def trim_history(messages, model="gpt-4o", budget=8000, keep_system=True):
    """오래된 대화부터 제거해 토큰 예산 안에 맞춘다."""
    system = [m for m in messages if m["role"] == "system"] if keep_system else []
    rest = [m for m in messages if m["role"] != "system"]
    while rest and count_chat_tokens(system + rest, model) > budget:
        rest.pop(0)          # 가장 오래된 메시지 제거
return system + rest🔹 tiktoken은
disallowed_special=() 또는 encode_ordinary로 특수 토큰 에러를 예방🔹 채팅 API는 메시지 포맷 오버헤드가 붙으므로 본문 합계보다 크다. 최종 기준은 API의 usage
🔹 단가는 설정 파일로 분리, 출력 토큰은 상한·통계·비율 중 하나로 추정
🔹 청크 분할은 문장 단위로 하고, 완성된 청크를 다시 세어 검증
🔹 숫자를 내는 도구엔 테스트와 "추정치" 표시로 신뢰를 더한다
여기까지 따라왔다면 이제 여러분 손에는 "글자 수 대충 곱하기"가 아니라, 모델별로 정확히 세고, 비용을 예측하고, 한도를 지키고, 문서를 알맞게 자르는 진짜 도구가 있어요. 처음엔 10줄짜리 스크립트였는데 말이죠! 다음 프로젝트에서 프롬프트 길이 때문에 고민될 때, 감 말고 계산기를 먼저 켜는 습관을 들여 보세요. 생각보다 많은 돈과 시간이 절약됩니다. 🌱
참고 자료
· openai/tiktoken (GitHub) — https://github.com/openai/tiktoken
· OpenAI Cookbook, "How to count tokens with tiktoken" — https://cookbook.openai.com/examples/how_to_count_tokens_with_tiktoken
· Hugging Face Transformers 문서, Tokenizer / Chat templates — https://huggingface.co/docs/transformers
· Anthropic 문서, Token counting — https://docs.anthropic.com/en/docs/build-with-claude/token-counting
· Google AI for Developers, Understand and count tokens — https://ai.google.dev/gemini-api/docs/tokens
· Sennrich et al., "Neural Machine Translation of Rare Words with Subword Units" (BPE) — https://arxiv.org/abs/1508.07909
관련 키워드

댓글 작성
이 글에 대한 여러분의 생각을 들려주세요
로그인이 필요합니다
댓글을 작성하려면 먼저 로그인해주세요.
댓글 0
지식인의 숲 - 지적 재산권 보호 고지
지적 재산권 보호 고지
- 저작권 및 소유권: 본 컨텐츠는 재능넷의 독점 AI 기술로 생성되었으며, 대한민국 저작권법 및 국제 저작권 협약에 의해 보호됩니다.
- AI 생성 컨텐츠의 법적 지위: 본 AI 생성 컨텐츠는 재능넷의 지적 창작물로 인정되며, 관련 법규에 따라 저작권 보호를 받습니다.
- 사용 제한: 재능넷의 명시적 서면 동의 없이 본 컨텐츠를 복제, 수정, 배포, 또는 상업적으로 활용하는 행위는 엄격히 금지됩니다.
- 데이터 수집 금지: 본 컨텐츠에 대한 무단 스크래핑, 크롤링, 및 자동화된 데이터 수집은 법적 제재의 대상이 됩니다.
- AI 학습 제한: 재능넷의 AI 생성 컨텐츠를 타 AI 모델 학습에 무단 사용하는 행위는 금지되며, 이는 지적 재산권 침해로 간주됩니다.
아직 댓글이 없습니다.