
Ver3.0 ⚡ 비동기 프로그래밍과 asyncio로 만드는 초고속 Python 애플리케이션 완벽 가이드
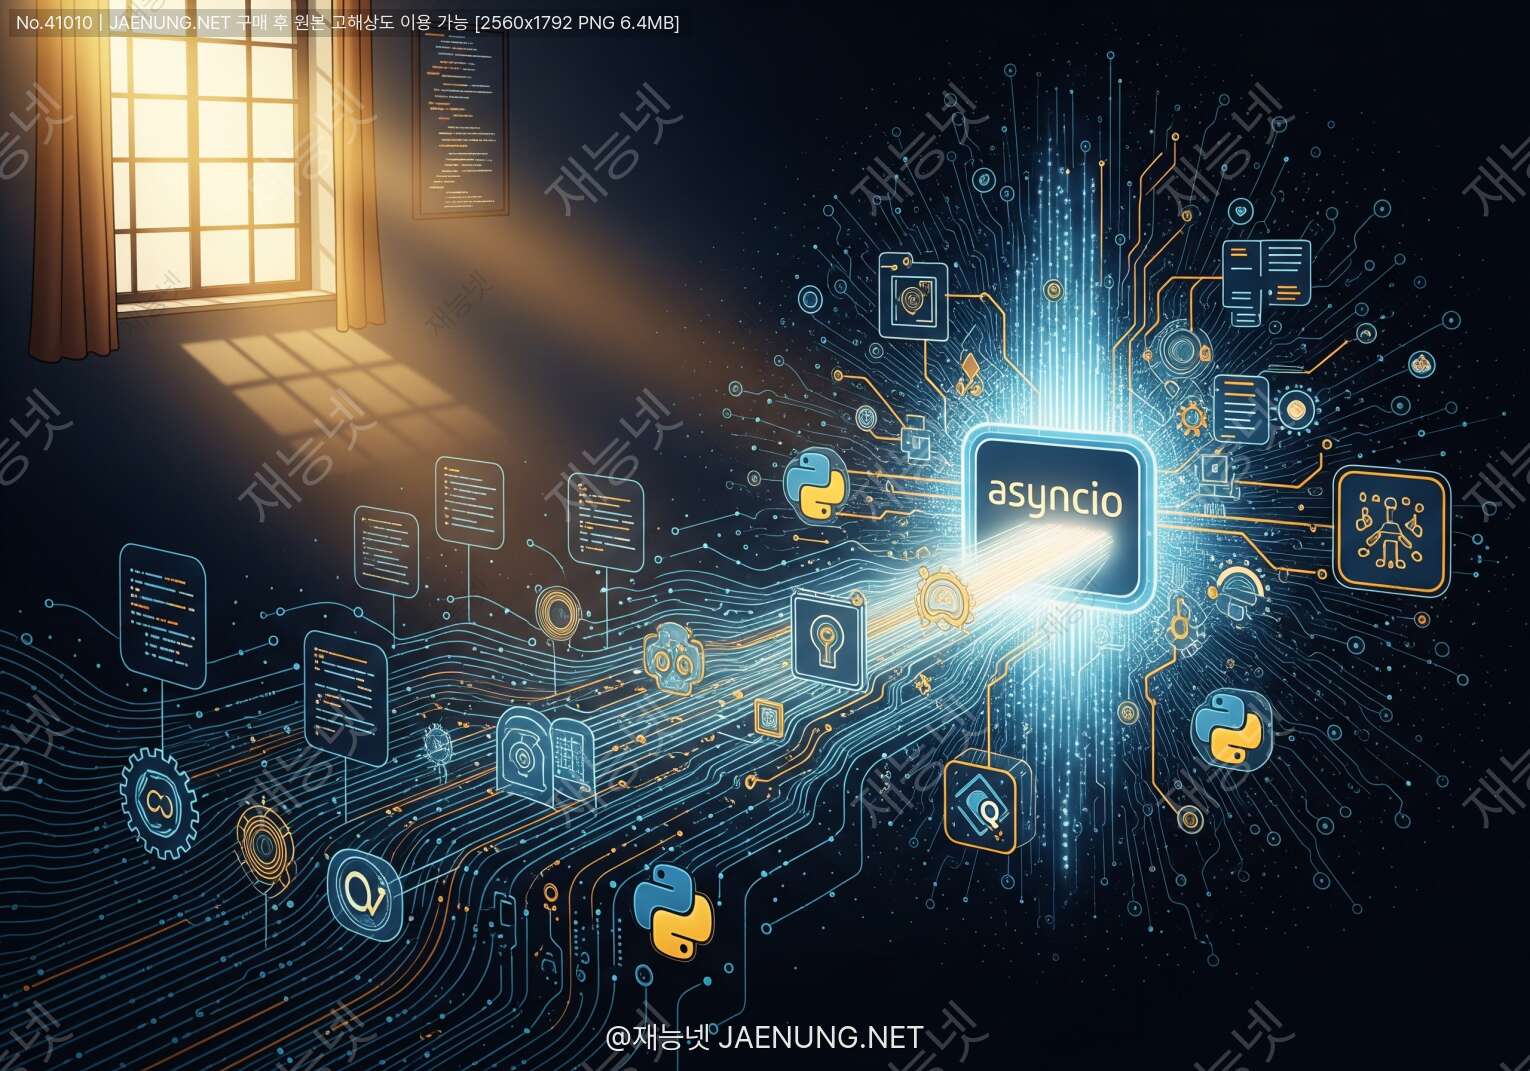
⚡ 비동기 프로그래밍과 asyncio로 만드는 초고속 Python 애플리케이션 완벽 가이드
동시성의 마법으로 당신의 코드를 10배 빠르게! 🚀
안녕! 👋 혹시 Python 코드가 느려서 답답했던 적 있어? 여러 작업을 동시에 처리하고 싶은데 어떻게 해야 할지 막막했던 경험 있지? 오늘은 그런 고민을 한 방에 날려줄 비동기 프로그래밍과 asyncio에 대해 친구처럼 편하게 이야기해볼게! 😊
사실 나도 처음엔 "비동기가 뭔데? 그냥 for문 돌리면 되는 거 아냐?"라고 생각했었어. 근데 알고 보니 완전 다른 세계더라고! 특히 웹 크롤링, API 호출, 데이터베이스 작업처럼 대기 시간이 긴 작업들을 다룰 때는 비동기 프로그래밍이 진짜 게임 체인저야. 🎮
🤔 비동기 프로그래밍, 도대체 뭐길래?
자, 일단 비유로 시작해볼까? 카페에서 커피를 주문한다고 생각해봐. ☕
동기 방식: 너는 카운터에서 커피를 주문하고, 바리스타가 커피를 만들 때까지 그 자리에서 꼼짝 않고 기다려. 커피가 나올 때까지 아무것도 못 해. 다음 손님도 당연히 기다려야 하고.
비동기 방식: 너는 주문하고 진동벨을 받아서 자리로 가. 그동안 책도 읽고, 친구랑 얘기도 하고, 폰도 보다가 벨이 울리면 그때 가서 커피를 받아오는 거야. 카페도 여러 주문을 동시에 처리할 수 있고!
바로 이게 비동기 프로그래밍의 핵심이야. 기다리는 시간을 낭비하지 않고 다른 일을 하는 거지! 🎯
💡 핵심 포인트 비동기 프로그래밍은 I/O 작업(파일 읽기/쓰기, 네트워크 통신, 데이터베이스 쿼리 등)에서 발생하는 대기 시간을 활용해서 다른 작업을 처리하는 프로그래밍 패러다임이야. CPU가 놀지 않고 계속 일할 수 있게 만드는 거지!
🐍 Python의 비동기 진화 과정
Python에서 비동기 프로그래밍이 어떻게 발전해왔는지 간단히 살펴볼게.
Python 2.x 시대: threading, multiprocessing 모듈로 동시성을 구현했어. 근데 GIL(Global Interpreter Lock) 때문에 진정한 병렬 처리는 어려웠지.
Python 3.4: asyncio 모듈이 표준 라이브러리에 추가됐어! 이때부터 본격적인 비동기 시대가 열렸지.
Python 3.5: async/await 키워드가 도입되면서 문법이 훨씬 직관적이고 깔끔해졌어. 이게 진짜 혁명이었어! 🎉
Python 3.7+: asyncio.run() 같은 고수준 API가 추가되면서 사용이 더 쉬워졌고, 성능도 크게 개선됐어.
🔧 asyncio의 핵심 개념들
asyncio를 제대로 이해하려면 몇 가지 핵심 개념을 알아야 해. 하나씩 친절하게 설명해줄게! 😊
1️⃣ 코루틴(Coroutine)
코루틴은 비동기 함수야. async def로 정의하고, 실행 중간에 멈췄다가 다시 시작할 수 있는 특별한 함수지. 일반 함수와 달리 await 키워드를 사용해서 다른 코루틴의 완료를 기다릴 수 있어.
import asyncio

async def make_coffee():
    print("☕ 커피 만들기 시작!")
    await asyncio.sleep(3)  # 3초 대기 (커피 내리는 시간)
    print("☕ 커피 완성!")
    return "아메리카노"

async def make_toast():
    print("🍞 토스트 만들기 시작!")
    await asyncio.sleep(2)  # 2초 대기 (토스트 굽는 시간)
    print("🍞 토스트 완성!")
    return "버터 토스트"

# 동기적으로 실행하면 5초 걸림
async def breakfast_sync():
    coffee = await make_coffee()
    toast = await make_toast()
    print(f"아침 식사 준비 완료: {coffee}, {toast}")

# 비동기적으로 실행하면 3초만 걸림!
async def breakfast_async():
    coffee_task = asyncio.create_task(make_coffee())
    toast_task = asyncio.create_task(make_toast())

    coffee = await coffee_task
    toast = await toast_task
    print(f"아침 식사 준비 완료: {coffee}, {toast}")

# 실행
asyncio.run(breakfast_async())
💚 Pro Tip 위 예제에서 breakfast_async()는 커피와 토스트를 동시에 만들기 시작해. 그래서 가장 오래 걸리는 작업(커피 3초)만큼만 시간이 걸려! 이게 바로 비동기의 힘이야. 🚀
2️⃣ 이벤트 루프(Event Loop)
이벤트 루프는 asyncio의 심장이야. 💓 모든 비동기 작업을 관리하고 스케줄링하는 중앙 제어 시스템이지.
이벤트 루프는 계속 돌면서 이런 일을 해:
- 실행 가능한 코루틴을 찾아서 실행
- I/O 작업이 완료되길 기다리는 코루틴 관리
- 완료된 작업의 결과를 해당 코루틴에 전달
- 모든 작업이 끝날 때까지 반복
Python 3.7부터는 asyncio.run()이 자동으로 이벤트 루프를 생성하고 관리해줘서 우리가 직접 신경 쓸 일이 거의 없어!
3️⃣ 태스크(Task)
태스크는 코루틴을 이벤트 루프에서 실행하도록 예약하는 객체야. asyncio.create_task()로 만들 수 있어.
async def fetch_data(url, delay):
    print(f"🌐 {url} 데이터 가져오기 시작")
    await asyncio.sleep(delay)
    print(f"✅ {url} 데이터 가져오기 완료")
    return f"{url}의 데이터"

async def main():
    # 여러 태스크를 동시에 실행
    task1 = asyncio.create_task(fetch_data("api.example.com/users", 2))
    task2 = asyncio.create_task(fetch_data("api.example.com/posts", 3))
    task3 = asyncio.create_task(fetch_data("api.example.com/comments", 1))

    # 모든 태스크가 완료될 때까지 대기
    results = await asyncio.gather(task1, task2, task3)
    print(f"모든 결과: {results}")

asyncio.run(main())
4️⃣ Future
Future는 아직 완료되지 않은 작업의 결과를 나타내는 객체야. 보통 직접 만들 일은 없고, 태스크나 다른 asyncio API가 내부적으로 사용해. 일종의 "약속"이라고 생각하면 돼 - "나중에 결과를 줄게!"라는 약속 말이야. 📝
⚡ asyncio의 강력한 기능들
asyncio.gather() - 여러 작업 동시 실행
여러 코루틴을 동시에 실행하고 모든 결과를 한 번에 받고 싶을 때 사용해. 진짜 자주 쓰는 함수야!
async def download_file(file_id):
    print(f"📥 파일 {file_id} 다운로드 시작")
    await asyncio.sleep(2)
    return f"file_{file_id}.dat"

async def main():
    # 10개 파일을 동시에 다운로드
    files = await asyncio.gather(
        *[download_file(i) for i in range(10)]
    )
    print(f"다운로드 완료: {files}")

asyncio.run(main())
⚠️ 주의사항 gather()는 하나의 작업이 실패하면 기본적으로 예외를 발생시켜. return_exceptions=True 옵션을 주면 예외도 결과 리스트에 포함시킬 수 있어!
asyncio.wait_for() - 타임아웃 설정
작업이 너무 오래 걸리면 취소하고 싶을 때 사용해. 실전에서 엄청 유용해!
async def slow_operation():
    await asyncio.sleep(10)
    return "완료!"

async def main():
    try:
        # 5초 안에 완료되지 않으면 TimeoutError 발생
        result = await asyncio.wait_for(slow_operation(), timeout=5.0)
        print(result)
    except asyncio.TimeoutError:
        print("⏰ 작업이 너무 오래 걸려서 취소했어요!")

asyncio.run(main())
asyncio.as_completed() - 완료되는 순서대로 처리
여러 작업 중 완료되는 것부터 바로바로 처리하고 싶을 때 사용해. gather()는 모든 작업이 끝날 때까지 기다리지만, as_completed()는 하나씩 완료될 때마다 결과를 줘.
async def process_item(item_id, delay):
    await asyncio.sleep(delay)
    return f"아이템 {item_id} 처리 완료"

async def main():
    tasks = [
        process_item(1, 3),
        process_item(2, 1),
        process_item(3, 2),
    ]

    # 완료되는 순서대로 출력 (2 -> 3 -> 1)
    for coro in asyncio.as_completed(tasks):
        result = await coro
        print(result)

asyncio.run(main())
🌐 실전 예제: 웹 크롤링
자, 이제 진짜 실전 예제를 볼 시간이야! 웹 크롤링은 비동기 프로그래밍의 대표적인 활용 사례야. aiohttp 라이브러리를 사용해서 여러 웹페이지를 동시에 가져와볼게.
import asyncio
import aiohttp
import time

# 동기 방식 (느림 🐢)
def fetch_sync(urls):
    import requests
    results = []
    for url in urls:
        response = requests.get(url)
        results.append(len(response.text))
    return results

# 비동기 방식 (빠름 🚀)
async def fetch_async(session, url):
    async with session.get(url) as response:
        html = await response.text()
        return len(html)

async def fetch_all_async(urls):
    async with aiohttp.ClientSession() as session:
        tasks = [fetch_async(session, url) for url in urls]
        return await asyncio.gather(*tasks)

# 테스트
urls = [
    'https://www.python.org',
    'https://www.github.com',
    'https://www.stackoverflow.com',
    'https://www.reddit.com',
    'https://www.wikipedia.org',
] * 5  # 25개 URL

# 동기 방식 실행
start = time.time()
sync_results = fetch_sync(urls)
sync_time = time.time() - start
print(f"동기 방식: {sync_time:.2f}초")

# 비동기 방식 실행
start = time.time()
async_results = asyncio.run(fetch_all_async(urls))
async_time = time.time() - start
print(f"비동기 방식: {async_time:.2f}초")
print(f"⚡ 속도 향상: {sync_time/async_time:.1f}배!")
🎯 결과 분석 실제로 실행해보면 비동기 방식이 5~10배 정도 빠른 걸 확인할 수 있어! 네트워크 대기 시간을 활용해서 여러 요청을 동시에 처리하기 때문이지. 이게 바로 비동기의 진가야! ✨
💾 데이터베이스 비동기 처리
데이터베이스 작업도 I/O 작업이라 비동기로 처리하면 엄청난 성능 향상을 볼 수 있어. asyncpg(PostgreSQL), aiomysql(MySQL), motor(MongoDB) 같은 비동기 드라이버들이 있어.
import asyncio
import asyncpg

async def fetch_users():
    # 데이터베이스 연결
    conn = await asyncpg.connect(
        user='user',
        password='password',
        database='mydb',
        host='localhost'
    )

    # 쿼리 실행
    rows = await conn.fetch('SELECT * FROM users WHERE active = $1', True)

    # 결과 처리
    for row in rows:
        print(f"User: {row['name']}, Email: {row['email']}")

    # 연결 종료
    await conn.close()

async def insert_users(users):
    conn = await asyncpg.connect(
        user='user',
        password='password',
        database='mydb',
        host='localhost'
    )

    # 여러 레코드를 동시에 삽입
    await conn.executemany(
        'INSERT INTO users(name, email) VALUES($1, $2)',
        users
    )

    await conn.close()

async def main():
    # 조회와 삽입을 동시에 실행
    await asyncio.gather(
        fetch_users(),
        insert_users([
            ('Alice', 'alice@example.com'),
            ('Bob', 'bob@example.com'),
        ])
    )

asyncio.run(main())
🎭 동기 코드와 비동기 코드 함께 사용하기
실전에서는 동기 라이브러리와 비동기 코드를 함께 써야 할 때가 많아. 이럴 때 사용하는 테크닉들을 알려줄게!
run_in_executor() - 동기 함수를 비동기로
CPU 집약적인 작업이나 동기 라이브러리를 비동기 코드에서 사용하고 싶을 때 run_in_executor()를 써.
import asyncio
import time
from concurrent.futures import ThreadPoolExecutor

def cpu_intensive_task(n):
    """CPU 집약적인 작업 (동기 함수)"""
    result = 0
    for i in range(n):
        result += i ** 2
    return result

async def main():
    loop = asyncio.get_event_loop()

    # ThreadPoolExecutor를 사용해서 동기 함수를 비동기로 실행
    with ThreadPoolExecutor() as executor:
        tasks = [
            loop.run_in_executor(executor, cpu_intensive_task, 1000000),
            loop.run_in_executor(executor, cpu_intensive_task, 2000000),
            loop.run_in_executor(executor, cpu_intensive_task, 3000000),
        ]

        results = await asyncio.gather(*tasks)
        print(f"결과: {results}")

asyncio.run(main())
💚 언제 ThreadPoolExecutor vs ProcessPoolExecutor?
- ThreadPoolExecutor: I/O 작업이나 가벼운 CPU 작업에 적합
- ProcessPoolExecutor: 무거운 CPU 집약적 작업에 적합 (GIL 우회)
대부분의 경우 ThreadPoolExecutor로 충분해!
asyncio.to_thread() - Python 3.9+
Python 3.9부터는 더 간단한 방법이 생겼어!
import asyncio

def blocking_io():
    print("파일 작업 시작")
    with open('large_file.txt', 'r') as f:
        return f.read()

async def main():
    # 동기 함수를 별도 스레드에서 실행
    result = await asyncio.to_thread(blocking_io)
    print(f"파일 크기: {len(result)} bytes")

asyncio.run(main())
🔄 비동기 컨텍스트 매니저와 이터레이터
async with와 async for도 알아두면 정말 유용해!
비동기 컨텍스트 매니저 (async with)
class AsyncDatabaseConnection:
    async def __aenter__(self):
        print("🔌 데이터베이스 연결 중...")
        await asyncio.sleep(1)
        print("✅ 연결 완료!")
        return self

    async def __aexit__(self, exc_type, exc_val, exc_tb):
        print("🔌 데이터베이스 연결 종료 중...")
        await asyncio.sleep(0.5)
        print("✅ 연결 종료 완료!")

    async def query(self, sql):
        print(f"🔍 쿼리 실행: {sql}")
        await asyncio.sleep(0.5)
        return ["결과1", "결과2", "결과3"]

async def main():
    async with AsyncDatabaseConnection() as db:
        results = await db.query("SELECT * FROM users")
        print(f"결과: {results}")

asyncio.run(main())
비동기 이터레이터 (async for)
class AsyncDataStream:
    def __init__(self, count):
        self.count = count
        self.current = 0

    def __aiter__(self):
        return self

    async def __anext__(self):
        if self.current >= self.count:
            raise StopAsyncIteration

        await asyncio.sleep(0.5)  # 데이터 가져오는 시간 시뮬레이션
        self.current += 1
        return f"데이터 {self.current}"

async def main():
    async for data in AsyncDataStream(5):
        print(f"받은 데이터: {data}")

asyncio.run(main())
🛡️ 에러 처리와 취소
비동기 프로그래밍에서 에러 처리는 정말 중요해! 제대로 안 하면 디버깅이 지옥이 될 수 있거든. 😱
기본 에러 처리
async def risky_operation(should_fail=False):
    await asyncio.sleep(1)
    if should_fail:
        raise ValueError("뭔가 잘못됐어요!")
    return "성공!"

async def main():
    tasks = [
        risky_operation(False),
        risky_operation(True),
        risky_operation(False),
    ]

    # 방법 1: 개별 처리
    for task in asyncio.as_completed(tasks):
        try:
            result = await task
            print(f"✅ {result}")
        except ValueError as e:
            print(f"❌ 에러 발생: {e}")

    # 방법 2: gather with return_exceptions
    results = await asyncio.gather(*tasks, return_exceptions=True)
    for i, result in enumerate(results):
        if isinstance(result, Exception):
            print(f"❌ 태스크 {i} 실패: {result}")
        else:
            print(f"✅ 태스크 {i} 성공: {result}")

asyncio.run(main())
태스크 취소
async def long_running_task():
    try:
        print("⏳ 긴 작업 시작...")
        await asyncio.sleep(10)
        print("✅ 작업 완료!")
    except asyncio.CancelledError:
        print("🛑 작업이 취소되었습니다!")
        # 정리 작업 수행
        raise  # 중요: 다시 raise 해야 함!

async def main():
    task = asyncio.create_task(long_running_task())

    # 2초 후 취소
    await asyncio.sleep(2)
    task.cancel()

    try:
        await task
    except asyncio.CancelledError:
        print("메인: 태스크 취소 확인")

asyncio.run(main())
⚙️ 성능 최적화 팁
✅ 해야 할 것들
• I/O 작업에 비동기 사용
• 적절한 동시 실행 수 제한
• 연결 풀링 활용
• 타임아웃 설정
• 에러 처리 철저히
• asyncio.gather() 적극 활용
• 비동기 라이브러리 우선 사용
❌ 하지 말아야 할 것들
• CPU 집약적 작업에 비동기 사용
• 무제한 동시 실행
• 동기 라이브러리를 await 없이 호출
• 에러 무시
• 너무 많은 태스크 생성
• time.sleep() 사용 (asyncio.sleep() 써야 함!)
• 블로킹 I/O 직접 호출
동시 실행 수 제한하기
수천 개의 요청을 동시에 보내면 서버가 죽을 수 있어. Semaphore로 제한하자!
async def fetch_with_limit(session, url, semaphore):
    async with semaphore:  # 동시 실행 수 제한
        async with session.get(url) as response:
            return await response.text()

async def main():
    # 최대 10개만 동시 실행
    semaphore = asyncio.Semaphore(10)

    urls = [f"https://api.example.com/item/{i}" for i in range(1000)]

    async with aiohttp.ClientSession() as session:
        tasks = [
            fetch_with_limit(session, url, semaphore)
            for url in urls
        ]
        results = await asyncio.gather(*tasks)

    print(f"총 {len(results)}개 처리 완료!")

asyncio.run(main())
🎯 실전 프로젝트: 비동기 웹 스크래퍼
자, 이제 배운 걸 다 합쳐서 실전 프로젝트를 만들어볼까? 여러 웹사이트에서 데이터를 수집하고, 처리하고, 데이터베이스에 저장하는 완전한 비동기 스크래퍼야!
import asyncio
import aiohttp
from bs4 import BeautifulSoup
import asyncpg
from typing import List, Dict
import logging

logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

class AsyncWebScraper:
    def __init__(self, max_concurrent=10):
        self.semaphore = asyncio.Semaphore(max_concurrent)
        self.session = None
        self.db_pool = None

    async def __aenter__(self):
        # HTTP 세션 생성
        self.session = aiohttp.ClientSession(
            timeout=aiohttp.ClientTimeout(total=30)
        )

        # 데이터베이스 연결 풀 생성
        self.db_pool = await asyncpg.create_pool(
            user='user',
            password='password',
            database='scraper_db',
            host='localhost',
            min_size=5,
            max_size=20
        )

        return self

    async def __aexit__(self, exc_type, exc_val, exc_tb):
        await self.session.close()
        await self.db_pool.close()

    async def fetch_page(self, url: str) -> str:
        """웹페이지 가져오기"""
        async with self.semaphore:
            try:
                async with self.session.get(url) as response:
                    if response.status == 200:
                        return await response.text()
                    else:
                        logger.warning(f"Failed to fetch {url}: {response.status}")
                        return None
            except Exception as e:
                logger.error(f"Error fetching {url}: {e}")
                return None

    async def parse_page(self, html: str, url: str) -> Dict:
        """HTML 파싱 (CPU 작업이므로 executor 사용)"""
        loop = asyncio.get_event_loop()
        return await loop.run_in_executor(
            None,
            self._parse_html,
            html,
            url
        )

    def _parse_html(self, html: str, url: str) -> Dict:
        """실제 파싱 로직 (동기 함수)"""
        soup = BeautifulSoup(html, 'html.parser')

        return {
            'url': url,
            'title': soup.title.string if soup.title else None,
            'links': [a['href'] for a in soup.find_all('a', href=True)],
            'text_length': len(soup.get_text())
        }

    async def save_to_db(self, data: Dict):
        """데이터베이스에 저장"""
        async with self.db_pool.acquire() as conn:
            await conn.execute('''
                INSERT INTO scraped_data(url, title, links, text_length)
                VALUES($1, $2, $3, $4)
                ON CONFLICT (url) DO UPDATE
                SET title = $2, links = $3, text_length = $4
            ''', data['url'], data['title'], data['links'], data['text_length'])

    async def scrape_url(self, url: str):
        """단일 URL 스크래핑"""
        logger.info(f"🔍 Scraping {url}")

        # 1. 페이지 가져오기
        html = await self.fetch_page(url)
        if not html:
            return None

        # 2. 파싱
        data = await self.parse_page(html, url)

        # 3. 저장
        await self.save_to_db(data)

        logger.info(f"✅ Completed {url}")
        return data

    async def scrape_urls(self, urls: List[str]):
        """여러 URL 동시 스크래핑"""
        tasks = [self.scrape_url(url) for url in urls]
        results = await asyncio.gather(*tasks, return_exceptions=True)

        # 결과 분석
        successful = sum(1 for r in results if r and not isinstance(r, Exception))
        failed = len(results) - successful

        logger.info(f"📊 완료: {successful}, 실패: {failed}")
        return results

async def main():
    urls = [
        'https://www.python.org',
        'https://www.github.com',
        'https://www.stackoverflow.com',
        # ... 더 많은 URL들
    ]

    async with AsyncWebScraper(max_concurrent=10) as scraper:
        results = await scraper.scrape_urls(urls)
        print(f"총 {len(results)}개 페이지 처리 완료!")

if __name__ == '__main__':
    asyncio.run(main())
🎓 이 프로젝트에서 배운 것들
• 컨텍스트 매니저로 리소스 관리
• Semaphore로 동시 실행 수 제한
• 연결 풀링으로 성능 최적화
• CPU 작업은 executor로 분리
• 에러 처리와 로깅
• 실전에서 바로 쓸 수 있는 구조!
이 코드를 기반으로 자신만의 스크래퍼를 만들어봐! 🚀
🔬 디버깅과 테스팅
비동기 코드는 디버깅이 까다로울 수 있어. 몇 가지 유용한 팁을 알려줄게!
asyncio 디버그 모드
import asyncio
import warnings

# 디버그 모드 활성화
asyncio.run(main(), debug=True)

# 또는 환경 변수로
# PYTHONASYNCIODEBUG=1 python script.py

# 경고를 에러로 변환
warnings.simplefilter('error', ResourceWarning)
비동기 코드 테스팅
import pytest
import asyncio

# pytest-asyncio 사용
@pytest.mark.asyncio
async def test_async_function():
    result = await my_async_function()
    assert result == expected_value

# 또는 직접 실행
def test_async_with_run():
    async def test_logic():
        result = await my_async_function()
        assert result == expected_value

    asyncio.run(test_logic())

# Mock 사용
from unittest.mock import AsyncMock

@pytest.mark.asyncio
async def test_with_mock():
    mock_api = AsyncMock(return_value="mocked data")
    result = await my_function_that_calls_api(mock_api)
    assert result == "processed mocked data"
📚 유용한 비동기 라이브러리들
asyncio 생태계에는 정말 많은 훌륭한 라이브러리들이 있어. 몇 가지 추천해줄게!
| 라이브러리 | 용도 | 특징 |
|---|---|---|
| aiohttp | HTTP 클라이언트/서버 | 가장 인기 있는 비동기 HTTP 라이브러리 |
| httpx | HTTP 클라이언트 | requests와 비슷한 API, 동기/비동기 모두 지원 |
| asyncpg | PostgreSQL | 가장 빠른 PostgreSQL 드라이버 |
| motor | MongoDB | 공식 MongoDB 비동기 드라이버 |
| aioredis | Redis | Redis 비동기 클라이언트 |
| aiokafka | Kafka | Kafka 비동기 클라이언트 |
| FastAPI | 웹 프레임워크 | 비동기 기반 초고속 API 프레임워크 |
| aiofiles | 파일 I/O | 비동기 파일 읽기/쓰기 |
🎨 FastAPI와 asyncio
FastAPI는 비동기를 완벽하게 지원하는 현대적인 웹 프레임워크야. 간단한 예제를 볼까?
from fastapi import FastAPI
import asyncio
import aiohttp

app = FastAPI()

@app.get("/")
async def root():
    return {"message": "Hello Async World!"}

@app.get("/fetch/{url:path}")
async def fetch_url(url: str):
    """외부 URL의 내용을 가져오는 엔드포인트"""
    async with aiohttp.ClientSession() as session:
        async with session.get(url) as response:
            content = await response.text()
            return {
                "url": url,
                "status": response.status,
                "length": len(content)
            }

@app.get("/parallel")
async def parallel_requests():
    """여러 API를 동시에 호출"""
    async def fetch_data(api_name, delay):
        await asyncio.sleep(delay)
        return {"api": api_name, "data": f"Data from {api_name}"}

    results = await asyncio.gather(
        fetch_data("API-1", 1),
        fetch_data("API-2", 2),
        fetch_data("API-3", 1.5),
    )

    return {"results": results}

# 실행: uvicorn main:app --reload
🚀 성능 비교: 동기 vs 비동기
실제로 얼마나 빠른지 벤치마크를 해볼까? 100개의 API 요청을 보내는 시나리오야.
import asyncio
import aiohttp
import requests
import time

URLS = [f"https://httpbin.org/delay/1" for _ in range(100)]

# 동기 버전
def sync_fetch_all():
    start = time.time()
    results = []
    for url in URLS:
        response = requests.get(url)
        results.append(response.status_code)
    elapsed = time.time() - start
    return elapsed, results

# 비동기 버전
async def async_fetch(session, url):
    async with session.get(url) as response:
        return response.status

async def async_fetch_all():
    start = time.time()
    async with aiohttp.ClientSession() as session:
        tasks = [async_fetch(session, url) for url in URLS]
        results = await asyncio.gather(*tasks)
    elapsed = time.time() - start
    return elapsed, results

# 테스트 실행
print("🐢 동기 방식 테스트 중...")
sync_time, sync_results = sync_fetch_all()
print(f"동기: {sync_time:.2f}초, 성공: {len(sync_results)}")

print("\n🚀 비동기 방식 테스트 중...")
async_time, async_results = asyncio.run(async_fetch_all())
print(f"비동기: {async_time:.2f}초, 성공: {len(async_results)}")

print(f"\n⚡ 속도 향상: {sync_time/async_time:.1f}배!")
print(f"⏱️ 시간 절약: {sync_time - async_time:.2f}초")
📊 예상 결과
동기: ~100초 (각 요청이 1초씩 순차 실행)
비동기: ~1-2초 (모든 요청이 동시 실행)
속도 향상: 약 50-100배! 🔥
이게 바로 비동기의 진정한 힘이야!
💡 실전 팁과 베스트 프랙티스
1. 언제 비동기를 사용해야 할까?
✅ 비동기가 좋은 경우
• 웹 스크래핑, API 호출
• 데이터베이스 쿼리
• 파일 I/O
• 네트워크 통신
• 웹소켓, 실시간 애플리케이션
• 마이크로서비스 간 통신
❌ 비동기가 별로인 경우
• CPU 집약적 계산 (이미지 처리, 머신러닝 등)
• 간단한 스크립트
• 동기 라이브러리만 사용 가능한 경우
• 팀원들이 비동기에 익숙하지 않은 경우
2. 일반적인 실수들
# ❌ 잘못된 예: time.sleep() 사용
async def bad_example():
    time.sleep(1)  # 전체 이벤트 루프를 블록!
    return "done"

# ✅ 올바른 예: asyncio.sleep() 사용
async def good_example():
    await asyncio.sleep(1)  # 다른 태스크가 실행될 수 있음
    return "done"

# ❌ 잘못된 예: await 없이 코루틴 호출
async def bad_example2():
    result = fetch_data()  # 코루틴 객체만 반환됨
    return result

# ✅ 올바른 예: await로 코루틴 실행
async def good_example2():
    result = await fetch_data()  # 실제로 실행됨
    return result

# ❌ 잘못된 예: 동기 라이브러리를 비동기에서 직접 호출
async def bad_example3():
    response = requests.get(url)  # 블로킹!
    return response

# ✅ 올바른 예: 비동기 라이브러리 사용
async def good_example3():
    async with aiohttp.ClientSession() as session:
        async with session.get(url) as response:
            return await response.text()
3. 메모리 관리
수천 개의 태스크를 만들면 메모리가 부족할 수 있어. 청크 단위로 처리하자!
async def process_in_chunks(items, chunk_size=100):
    """아이템을 청크 단위로 처리"""
    for i in range(0, len(items), chunk_size):
        chunk = items[i:i + chunk_size]
        tasks = [process_item(item) for item in chunk]
        results = await asyncio.gather(*tasks)
        # 결과 처리
        yield results

async def main():
    items = range(10000)  # 10,000개 아이템

    async for chunk_results in process_in_chunks(items, chunk_size=100):
        print(f"청크 처리 완료: {len(chunk_results)}개")

asyncio.run(main())
🌟 재능넷에서 비동기 프로그래밍 배우기
비동기 프로그래밍이 처음엔 어렵게 느껴질 수 있어. 하지만 걱정 마! 재능넷(https://www.jaenung.net)에는 Python 비동기 프로그래밍을 가르쳐줄 수 있는 전문가들이 많아. 🎓
1:1 코칭을 받으면서 실전 프로젝트를 함께 만들어보는 것도 좋은 방법이야. 특히 웹 크롤링이나 API 서버 개발 같은 실무 프로젝트를 통해 배우면 훨씬 빠르게 실력이 늘어!
또한 재능넷에서는 코드 리뷰나 프로젝트 멘토링 서비스도 찾을 수 있어서, 혼자 공부하다가 막힐 때 정말 유용해. 💪
🎯 마무리하며
자, 여기까지 비동기 프로그래밍과 asyncio에 대해 알아봤어! 정말 긴 여정이었지? 😅
처음엔 복잡해 보이지만, 핵심 개념만 이해하면 생각보다 어렵지 않아. async/await, 코루틴, 태스크, 이벤트 루프... 이 네 가지만 확실히 이해하면 나머지는 자연스럽게 따라와!
기억해야 할 핵심 포인트들:
🎯 비동기는 I/O 작업에 최적화되어 있어
🎯 await 키워드를 빼먹지 말자
🎯 동기 라이브러리는 run_in_executor()로 감싸자
🎯 에러 처리와 타임아웃 설정은 필수
🎯 동시 실행 수를 적절히 제한하자
🎯 실전 프로젝트로 연습하는 게 최고!
비동기 프로그래밍은 현대 Python 개발에서 필수 스킬이 되어가고 있어. 특히 웹 개발, 데이터 엔지니어링, DevOps 분야에서는 거의 필수지. 지금 배워두면 나중에 정말 큰 도움이 될 거야! 🚀
혹시 더 궁금한 게 있거나 막히는 부분이 있다면, 직접 코드를 짜보면서 실험해봐. 그게 가장 빠른 학습 방법이야. 그리고 공식 문서(https://docs.python.org/3/library/asyncio.html)도 정말 잘 되어 있으니까 참고하면 좋아!
자, 이제 당신의 Python 코드를 10배 빠르게 만들어볼 시간이야! 화이팅! 💪✨
🎉 축하해요!
이제 당신은 Python 비동기 프로그래밍의 기초부터 실전까지 모두 배웠어요!
이 지식을 바탕으로 멋진 고성능 애플리케이션을 만들어보세요! 🚀✨

댓글 작성
이 글에 대한 여러분의 생각을 들려주세요
로그인이 필요합니다
댓글을 작성하려면 먼저 로그인해주세요.
댓글 0
지식인의 숲 - 지적 재산권 보호 고지
지적 재산권 보호 고지
- 저작권 및 소유권: 본 컨텐츠는 재능넷의 독점 AI 기술로 생성되었으며, 대한민국 저작권법 및 국제 저작권 협약에 의해 보호됩니다.
- AI 생성 컨텐츠의 법적 지위: 본 AI 생성 컨텐츠는 재능넷의 지적 창작물로 인정되며, 관련 법규에 따라 저작권 보호를 받습니다.
- 사용 제한: 재능넷의 명시적 서면 동의 없이 본 컨텐츠를 복제, 수정, 배포, 또는 상업적으로 활용하는 행위는 엄격히 금지됩니다.
- 데이터 수집 금지: 본 컨텐츠에 대한 무단 스크래핑, 크롤링, 및 자동화된 데이터 수집은 법적 제재의 대상이 됩니다.
- AI 학습 제한: 재능넷의 AI 생성 컨텐츠를 타 AI 모델 학습에 무단 사용하는 행위는 금지되며, 이는 지적 재산권 침해로 간주됩니다.

아직 댓글이 없습니다.