
Ver3.0 🎨 CLIP 모델로 이미지와 텍스트를 자유자재로 매칭하는 마법 같은 기술
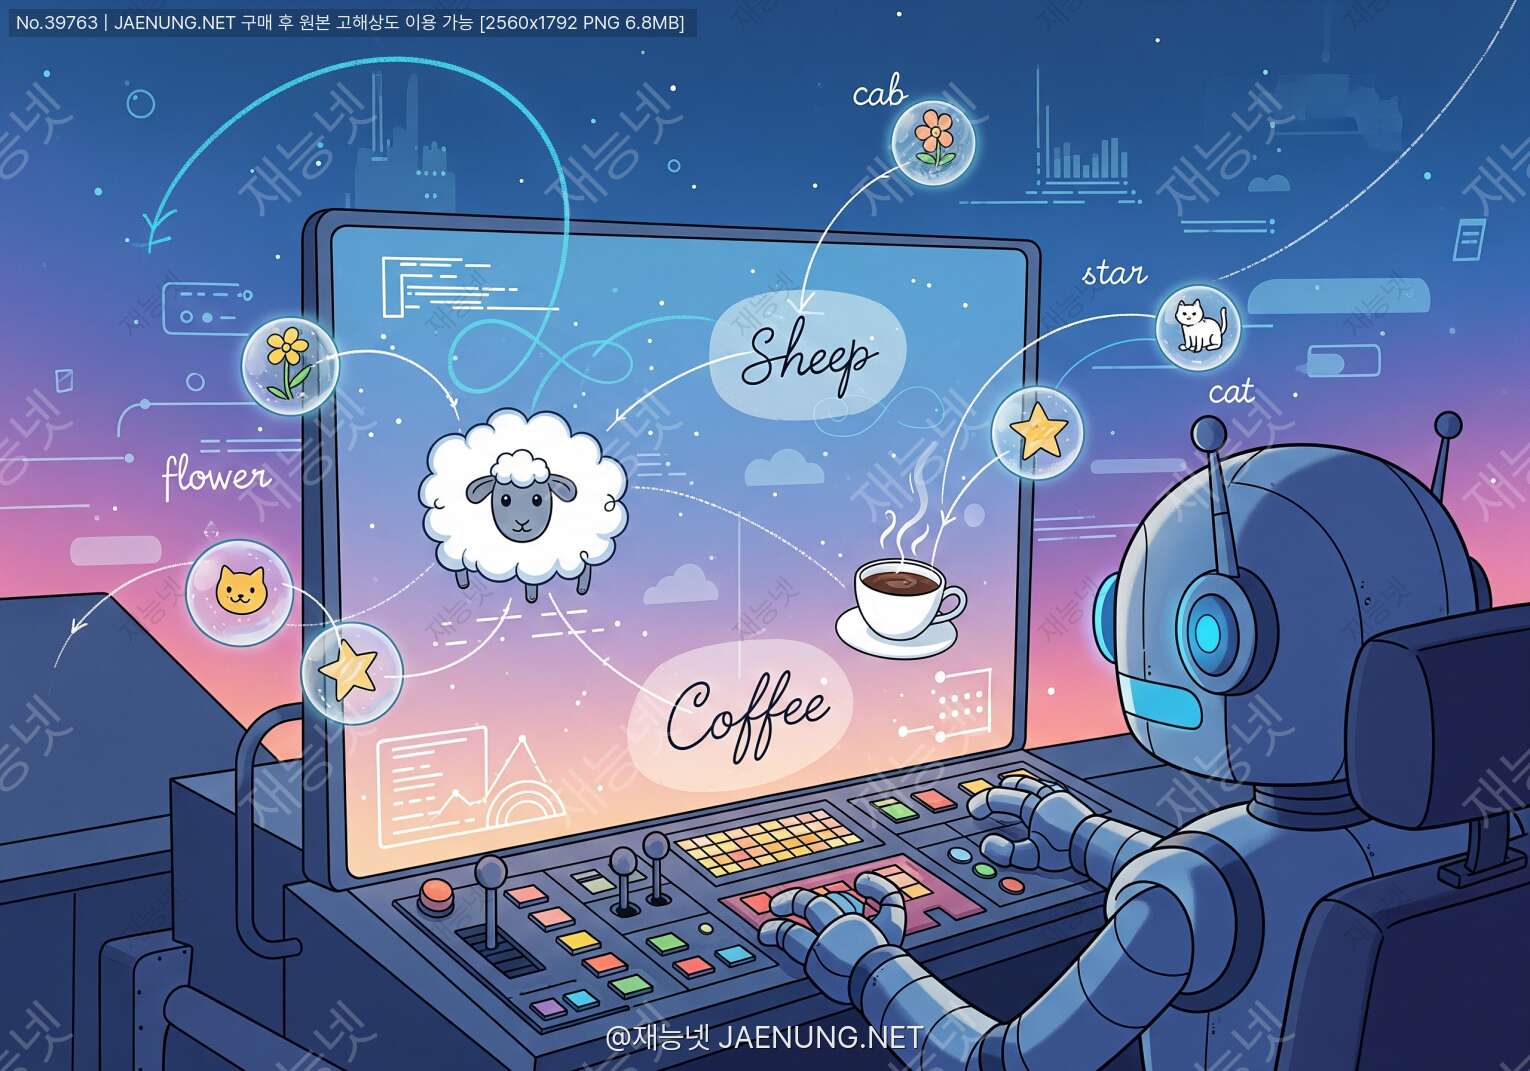
🎨 CLIP 모델로 이미지와 텍스트를 자유자재로 매칭하는 마법 같은 기술
OpenAI가 선보인 혁신적인 멀티모달 AI, 그 원리부터 실전 구현까지 완벽 가이드 🚀
🌟 CLIP, 대체 뭐길래 이렇게 난리야?
안녕, 친구! 😊 오늘은 정말 신나는 주제를 가지고 왔어. 바로 CLIP 모델이라는 녀석인데, 이게 진짜 혁명적이야. 상상해봐, 컴퓨터한테 "귀여운 강아지가 공원에서 뛰어노는 사진"이라고 말하면, 수천 장의 이미지 중에서 딱 그 장면을 찾아내는 거야! 🐕✨
2021년 초, OpenAI가 CLIP(Contrastive Language-Image Pre-training)을 발표했을 때 AI 커뮤니티는 완전히 뒤집혔어. 왜냐고? 기존의 이미지 인식 모델들은 "개", "고양이", "자동차" 같은 정해진 카테고리만 인식할 수 있었거든. 근데 CLIP은 완전히 다른 접근을 했어. 자연어로 된 설명과 이미지를 동시에 학습해서, 한 번도 본 적 없는 개념도 이해할 수 있게 된 거지! 🎯
이게 전부야. 간단하지? 하지만 이 간단한 아이디어가 4억 개의 이미지-텍스트 쌍으로 학습되면서 엄청난 능력을 갖게 됐어. 마치 사람이 사진을 보고 설명을 듣듯이, CLIP도 그렇게 배운 거야! 🧠
🔍 CLIP의 작동 원리: 마법 같지만 과학이야
자, 이제 본격적으로 CLIP이 어떻게 작동하는지 파헤쳐보자! 🕵️ 복잡해 보이지만, 차근차근 따라오면 "아하!" 하는 순간이 올 거야.
CLIP의 핵심은 두 개의 인코더야. 하나는 이미지를 처리하고, 다른 하나는 텍스트를 처리해. 그리고 이 둘이 만들어낸 결과물을 같은 공간(Embedding Space)에 놓는 거지. 마치 서로 다른 언어를 쓰는 사람들이 공통의 언어로 대화하는 것처럼 말이야! 🌐
📸 이미지 인코더: 시각 정보의 번역가
이미지 인코더는 주로 Vision Transformer(ViT)나 ResNet 같은 구조를 사용해. OpenAI의 원본 CLIP은 두 가지 버전을 제공하는데:
1. ResNet 기반 (RN50, RN101 등)
전통적인 CNN 구조로, 이미지를 여러 단계의 합성곱 레이어를 거쳐 처리해. 안정적이고 검증된 방식이지! 🏛️
2. Vision Transformer 기반 (ViT-B/32, ViT-L/14 등)
이미지를 작은 패치로 나눠서 Transformer로 처리하는 최신 방식. 더 강력하지만 계산량이 많아. 💪
어떤 구조를 쓰든, 최종 목표는 같아. 이미지를 고정된 크기의 벡터로 변환하는 거야. 예를 들어, 512차원 벡터로 만들면, 그 벡터가 이미지의 모든 특징을 담고 있는 거지!
📝 텍스트 인코더: 언어의 마법사
텍스트 인코더는 Transformer 구조를 사용해. GPT와 비슷한 구조라고 생각하면 돼! 텍스트를 토큰으로 나누고, 각 토큰의 의미와 문맥을 파악해서 최종적으로 하나의 벡터로 만들어내는 거야. 📚
재미있는 건, CLIP의 텍스트 인코더는 최대 77개의 토큰까지 처리할 수 있어. 그러니까 꽤 긴 문장도 이해할 수 있다는 뜻이지! "A photo of a golden retriever puppy playing with a red ball in a sunny park during autumn"처럼 구체적인 설명도 가능해. 🍂
🎯 대조 학습(Contrastive Learning): 핵심 중의 핵심
자, 이제 가장 중요한 부분이야! CLIP이 어떻게 학습하는지 알아보자. 🎓
상상해봐. 배치(batch) 안에 32개의 이미지-텍스트 쌍이 있어. 각 이미지는 자신과 매칭되는 텍스트가 하나씩 있지. CLIP의 목표는 뭘까?
매칭되는 이미지-텍스트 쌍의 벡터는 가깝게, 매칭되지 않는 쌍의 벡터는 멀게 만드는 거야! 🎯
구체적으로 설명하면:
2️⃣ 32개 텍스트를 텍스트 인코더에 넣어 → 32개의 텍스트 벡터 생성
3️⃣ 32×32 = 1,024개의 가능한 조합 중에서
4️⃣ 정답 쌍 32개는 유사도를 높이고 (대각선 요소)
5️⃣ 오답 쌍 992개는 유사도를 낮춰! (비대각선 요소)
이렇게 하면 모델이 "어떤 이미지와 텍스트가 서로 관련있는지" 배우게 돼! 🧠
이 과정을 수식으로 표현하면 InfoNCE Loss를 사용하는데, 간단히 말하면 "정답은 확률을 높이고, 오답은 확률을 낮춰라"는 거야. 마치 객관식 시험에서 정답을 찾는 것처럼! ✅
💻 실전 구현: 코드로 만나는 CLIP
이론은 충분히 배웠으니, 이제 진짜 코드를 작성해보자! 🚀 Python과 PyTorch를 사용할 거야. 걱정 마, 하나하나 설명해줄게!
🔧 환경 설정: 준비운동부터
먼저 필요한 라이브러리들을 설치해야 해. 터미널을 열고 다음 명령어를 입력해봐:
pip install torch torchvision
pip install ftfy regex tqdm
pip install git+https://github.com/openai/CLIP.git
ftfy는 텍스트 정규화를 위한 라이브러리고, regex는 정규표현식, tqdm은 진행 상황 표시를 위한 거야. 마지막 줄은 OpenAI의 공식 CLIP 라이브러리를 설치하는 명령어지! 📦
🎬 기본 사용법: Hello CLIP!
가장 간단한 예제부터 시작해보자. 이미지 하나와 여러 텍스트 중에서 가장 잘 매칭되는 걸 찾는 코드야:
import torch
import clip
from PIL import Image

# 디바이스 설정 (GPU 있으면 GPU, 없으면 CPU)
device = "cuda" if torch.cuda.is_available() else "cpu"

# CLIP 모델 로드
model, preprocess = clip.load("ViT-B/32", device=device)

# 이미지 로드 및 전처리
image = preprocess(Image.open("dog.jpg")).unsqueeze(0).to(device)

# 후보 텍스트들
text_candidates = [
    "a photo of a dog",
    "a photo of a cat",
    "a photo of a car",
    "a photo of a bird"
]

# 텍스트 토큰화
text = clip.tokenize(text_candidates).to(device)

# 추론 (inference)
with torch.no_grad():
    image_features = model.encode_image(image)
    text_features = model.encode_text(text)

    # 유사도 계산
    logits_per_image, logits_per_text = model(image, text)
    probs = logits_per_image.softmax(dim=-1).cpu().numpy()

# 결과 출력
print("각 텍스트의 확률:")
for i, candidate in enumerate(text_candidates):
    print(f"{candidate}: {probs[0][i]*100:.2f}%")
이 코드를 실행하면, 각 텍스트가 이미지와 얼마나 잘 매칭되는지 확률로 보여줘! 만약 dog.jpg가 정말 강아지 사진이라면, "a photo of a dog"가 90% 이상의 높은 확률을 보일 거야. 🐕
torch.no_grad(): 그래디언트 계산을 끄는 거야. 추론할 때는 필요 없거든!
softmax(dim=-1): 로짓 값을 확률로 변환해. 모든 확률의 합은 1이 돼!
🔎 이미지 검색 시스템 만들기
이제 좀 더 실용적인 걸 만들어보자! 여러 이미지 중에서 텍스트 쿼리와 가장 잘 맞는 이미지를 찾는 검색 시스템이야. 마치 구글 이미지 검색처럼! 🔍
import os
import torch
import clip
from PIL import Image
import numpy as np

class ImageSearchEngine:
    def __init__(self, model_name="ViT-B/32"):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load(model_name, device=self.device)
        self.image_features = None
        self.image_paths = []

    def index_images(self, image_folder):
        """이미지 폴더의 모든 이미지를 인덱싱"""
        print(f"📁 {image_folder}의 이미지들을 인덱싱 중...")

        image_files = [f for f in os.listdir(image_folder)
                      if f.lower().endswith(('.png', '.jpg', '.jpeg'))]

        features_list = []

        for img_file in image_files:
            img_path = os.path.join(image_folder, img_file)
            image = self.preprocess(Image.open(img_path)).unsqueeze(0).to(self.device)

            with torch.no_grad():
                features = self.model.encode_image(image)
                features /= features.norm(dim=-1, keepdim=True)  # 정규화

            features_list.append(features)
            self.image_paths.append(img_path)

        self.image_features = torch.cat(features_list, dim=0)
        print(f"✅ {len(self.image_paths)}개 이미지 인덱싱 완료!")

    def search(self, query, top_k=5):
        """텍스트 쿼리로 이미지 검색"""
        text = clip.tokenize([query]).to(self.device)

        with torch.no_grad():
            text_features = self.model.encode_text(text)
            text_features /= text_features.norm(dim=-1, keepdim=True)

        # 코사인 유사도 계산
        similarity = (text_features @ self.image_features.T).squeeze(0)

        # 상위 k개 결과
        top_indices = similarity.argsort(descending=True)[:top_k]

        results = []
        for idx in top_indices:
            results.append({
                'path': self.image_paths[idx],
                'score': similarity[idx].item()
            })

        return results

# 사용 예시
if __name__ == "__main__":
    engine = ImageSearchEngine()
    engine.index_images("./my_photos")

    query = "a beautiful sunset over the ocean"
    results = engine.search(query, top_k=3)

    print(f"\n🔍 검색어: '{query}'")
    print("=" * 50)
    for i, result in enumerate(results, 1):
        print(f"{i}. {result['path']}")
        print(f"   유사도: {result['score']:.4f}")
이 코드는 진짜 실용적이야! 🎉 index_images() 메서드로 이미지들을 미리 인코딩해두고, search() 메서드로 원하는 이미지를 찾을 수 있어. 코사인 유사도를 사용해서 가장 비슷한 이미지를 찾는 거지!
특히 정규화(normalization)가 중요해. 벡터를 정규화하면 코사인 유사도를 내적(dot product)으로 간단히 계산할 수 있거든! 수학적으로 효율적이야. 📐
🎨 제로샷 이미지 분류기
CLIP의 가장 강력한 기능 중 하나가 바로 제로샷 분류(Zero-shot Classification)야! 학습 데이터 없이도 새로운 카테고리를 분류할 수 있어. 어떻게? 텍스트로 카테고리를 설명하면 되거든! 🎯
class ZeroShotClassifier:
    def __init__(self, model_name="ViT-B/32"):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load(model_name, device=self.device)

    def classify(self, image_path, categories, template="a photo of a {}"):
        """이미지를 주어진 카테고리로 분류"""
        # 이미지 로드
        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        # 카테고리별 텍스트 생성
        texts = [template.format(cat) for cat in categories]
        text_tokens = clip.tokenize(texts).to(self.device)

        # 인코딩
        with torch.no_grad():
            image_features = self.model.encode_image(image)
            text_features = self.model.encode_text(text_tokens)

            # 정규화
            image_features /= image_features.norm(dim=-1, keepdim=True)
            text_features /= text_features.norm(dim=-1, keepdim=True)

            # 유사도 계산 및 확률 변환
            similarity = (100.0 * image_features @ text_features.T).softmax(dim=-1)

        # 결과 정리
        results = []
        for i, category in enumerate(categories):
            results.append({
                'category': category,
                'probability': similarity[0, i].item()
            })

        # 확률 순으로 정렬
        results.sort(key=lambda x: x['probability'], reverse=True)
        return results

# 사용 예시
classifier = ZeroShotClassifier()

# 동물 분류
animal_categories = ["dog", "cat", "bird", "fish", "horse", "elephant"]
results = classifier.classify("animal.jpg", animal_categories)

print("🐾 동물 분류 결과:")
for result in results:
    print(f"{result['category']}: {result['probability']*100:.2f}%")

# 감정 분류 (같은 이미지로!)
emotion_categories = ["happy", "sad", "angry", "surprised", "neutral"]
emotion_template = "a {} looking animal"
results = classifier.classify("animal.jpg", emotion_categories, emotion_template)

print("\n😊 감정 분류 결과:")
for result in results:
    print(f"{result['category']}: {result['probability']*100:.2f}%")
이 코드의 멋진 점은 template 파라미터야! 템플릿을 바꾸면 같은 이미지를 다른 관점에서 분류할 수 있어. "a photo of a {}"는 일반적인 분류에 좋고, "a {} looking animal"은 감정 분류에 적합하지. 유연성이 정말 좋아! 🎭
⚡ 성능 최적화: 더 빠르고 효율적으로
CLIP은 강력하지만, 제대로 최적화하지 않으면 느릴 수 있어. 특히 수천, 수만 개의 이미지를 처리할 때는 최적화가 필수야! 🚀 실전에서 쓸 수 있는 팁들을 알려줄게.
🎯 배치 처리로 속도 올리기
이미지를 하나씩 처리하는 건 비효율적이야. GPU는 병렬 처리에 최적화되어 있거든! 여러 이미지를 한 번에 처리하는 배치 처리를 사용하면 속도가 엄청 빨라져. 💨
def batch_encode_images(model, preprocess, image_paths, batch_size=32, device="cuda"):
    """이미지들을 배치로 인코딩"""
    all_features = []

    for i in range(0, len(image_paths), batch_size):
        batch_paths = image_paths[i:i+batch_size]

        # 배치 이미지 로드
        images = []
        for path in batch_paths:
            image = preprocess(Image.open(path))
            images.append(image)

        # 텐서로 변환
        batch_tensor = torch.stack(images).to(device)

        # 인코딩
        with torch.no_grad():
            features = model.encode_image(batch_tensor)
            features /= features.norm(dim=-1, keepdim=True)

        all_features.append(features)

    return torch.cat(all_features, dim=0)

# 사용 예시
image_paths = ["img1.jpg", "img2.jpg", ..., "img1000.jpg"]
features = batch_encode_images(model, preprocess, image_paths, batch_size=64)
배치 크기는 GPU 메모리에 따라 조절해야 해. RTX 3090 같은 고성능 GPU는 64~128도 가능하지만, 일반 GPU는 16~32가 적당해. 메모리 부족 에러가 나면 배치 크기를 줄여봐! 🎮
💾 특징 벡터 캐싱
같은 이미지를 여러 번 인코딩하는 건 낭비야! 한 번 계산한 특징 벡터는 저장해두고 재사용하자. 🗄️
import pickle
import hashlib

class FeatureCache:
    def __init__(self, cache_file="feature_cache.pkl"):
        self.cache_file = cache_file
        self.cache = self._load_cache()

    def _load_cache(self):
        """캐시 파일 로드"""
        try:
            with open(self.cache_file, 'rb') as f:
                return pickle.load(f)
        except FileNotFoundError:
            return {}

    def _save_cache(self):
        """캐시 파일 저장"""
        with open(self.cache_file, 'wb') as f:
            pickle.dump(self.cache, f)

    def _get_file_hash(self, file_path):
        """파일 해시 계산 (캐시 키로 사용)"""
        with open(file_path, 'rb') as f:
            return hashlib.md5(f.read()).hexdigest()

    def get_feature(self, file_path):
        """캐시에서 특징 벡터 가져오기"""
        file_hash = self._get_file_hash(file_path)
        return self.cache.get(file_hash)

    def set_feature(self, file_path, feature):
        """특징 벡터를 캐시에 저장"""
        file_hash = self._get_file_hash(file_path)
        self.cache[file_hash] = feature.cpu().numpy()
        self._save_cache()

# 사용 예시
cache = FeatureCache()

def encode_with_cache(model, preprocess, image_path, device="cuda"):
    # 캐시 확인
    cached_feature = cache.get_feature(image_path)
    if cached_feature is not None:
        print(f"✅ 캐시에서 로드: {image_path}")
        return torch.from_numpy(cached_feature).to(device)

    # 캐시 없으면 새로 계산
    print(f"🔄 새로 계산: {image_path}")
    image = preprocess(Image.open(image_path)).unsqueeze(0).to(device)
    with torch.no_grad():
        feature = model.encode_image(image)
        feature /= feature.norm(dim=-1, keepdim=True)

    # 캐시에 저장
    cache.set_feature(image_path, feature)
    return feature
이 방식은 특히 개발 단계에서 유용해! 같은 이미지로 여러 번 테스트할 때 시간을 엄청 절약할 수 있거든. ⏰
🔧 모델 양자화(Quantization)
모델 크기를 줄이고 추론 속도를 높이려면 양자화를 고려해봐. FP32(32비트 부동소수점)를 FP16이나 INT8로 변환하는 거야. 정확도는 약간 떨어지지만, 속도는 2~4배 빨라질 수 있어! ⚡
# FP16 (Half Precision) 사용
model, preprocess = clip.load("ViT-B/32", device="cuda")
model = model.half()  # FP16으로 변환

# 이미지도 FP16으로
image = preprocess(Image.open("test.jpg")).unsqueeze(0).to("cuda").half()

with torch.no_grad():
    features = model.encode_image(image)
🎨 실전 프로젝트: 나만의 이미지 검색 웹앱 만들기
이제 배운 걸 종합해서 실제로 쓸 수 있는 웹 애플리케이션을 만들어보자! Flask를 사용해서 간단한 이미지 검색 서비스를 구축할 거야. 🌐
📦 프로젝트 구조
image_search_app/
├── app.py                 # Flask 메인 애플리케이션
├── clip_engine.py         # CLIP 검색 엔진
├── templates/
│   └── index.html        # 웹 인터페이스
├── static/
│   ├── uploads/          # 업로드된 이미지
│   └── style.css         # 스타일시트
└── requirements.txt      # 의존성 패키지
🔧 clip_engine.py: 검색 엔진 코어
import torch
import clip
from PIL import Image
import os
import pickle

class CLIPSearchEngine:
    def __init__(self, model_name="ViT-B/32", cache_dir="./cache"):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        print(f"🚀 디바이스: {self.device}")

        self.model, self.preprocess = clip.load(model_name, device=self.device)
        self.cache_dir = cache_dir
        os.makedirs(cache_dir, exist_ok=True)

        self.image_features = None
        self.image_paths = []
        self._load_index()

    def _load_index(self):
        """저장된 인덱스 로드"""
        index_path = os.path.join(self.cache_dir, "index.pkl")
        if os.path.exists(index_path):
            with open(index_path, 'rb') as f:
                data = pickle.load(f)
                self.image_features = data['features'].to(self.device)
                self.image_paths = data['paths']
            print(f"✅ 인덱스 로드 완료: {len(self.image_paths)}개 이미지")

    def _save_index(self):
        """인덱스 저장"""
        index_path = os.path.join(self.cache_dir, "index.pkl")
        data = {
            'features': self.image_features.cpu(),
            'paths': self.image_paths
        }
        with open(index_path, 'wb') as f:
            pickle.dump(data, f)
        print("💾 인덱스 저장 완료")

    def add_image(self, image_path):
        """새 이미지 추가"""
        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        with torch.no_grad():
            features = self.model.encode_image(image)
            features /= features.norm(dim=-1, keepdim=True)

        if self.image_features is None:
            self.image_features = features
        else:
            self.image_features = torch.cat([self.image_features, features], dim=0)

        self.image_paths.append(image_path)
        self._save_index()

    def search_by_text(self, query, top_k=10):
        """텍스트로 검색"""
        if self.image_features is None:
            return []

        text = clip.tokenize([query]).to(self.device)

        with torch.no_grad():
            text_features = self.model.encode_text(text)
            text_features /= text_features.norm(dim=-1, keepdim=True)

        similarity = (text_features @ self.image_features.T).squeeze(0)
        top_indices = similarity.argsort(descending=True)[:top_k]

        results = []
        for idx in top_indices:
            results.append({
                'path': self.image_paths[idx],
                'score': similarity[idx].item()
            })

        return results

    def search_by_image(self, image_path, top_k=10):
        """이미지로 검색"""
        if self.image_features is None:
            return []

        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        with torch.no_grad():
            query_features = self.model.encode_image(image)
            query_features /= query_features.norm(dim=-1, keepdim=True)

        similarity = (query_features @ self.image_features.T).squeeze(0)
        top_indices = similarity.argsort(descending=True)[1:top_k+1]  # 자기 자신 제외

        results = []
        for idx in top_indices:
            results.append({
                'path': self.image_paths[idx],
                'score': similarity[idx].item()
            })

        return results
🌐 app.py: Flask 웹 서버
from flask import Flask, render_template, request, jsonify
import os
from werkzeug.utils import secure_filename
from clip_engine import CLIPSearchEngine

app = Flask(__name__)
app.config['UPLOAD_FOLDER'] = './static/uploads'
app.config['MAX_CONTENT_LENGTH'] = 16 * 1024 * 1024  # 16MB 제한

os.makedirs(app.config['UPLOAD_FOLDER'], exist_ok=True)

# CLIP 엔진 초기화
engine = CLIPSearchEngine()

@app.route('/')
def index():
    return render_template('index.html')

@app.route('/upload', methods=['POST'])
def upload_image():
    """이미지 업로드 및 인덱싱"""
    if 'file' not in request.files:
        return jsonify({'error': '파일이 없습니다'}), 400

    file = request.files['file']
    if file.filename == '':
        return jsonify({'error': '파일이 선택되지 않았습니다'}), 400

    if file:
        filename = secure_filename(file.filename)
        filepath = os.path.join(app.config['UPLOAD_FOLDER'], filename)
        file.save(filepath)

        # 인덱스에 추가
        engine.add_image(filepath)

        return jsonify({
            'success': True,
            'message': '이미지가 추가되었습니다',
            'path': filepath
        })

@app.route('/search/text', methods=['POST'])
def search_text():
    """텍스트 검색"""
    data = request.get_json()
    query = data.get('query', '')
    top_k = data.get('top_k', 10)

    results = engine.search_by_text(query, top_k)

    return jsonify({
        'results': results,
        'count': len(results)
    })

@app.route('/search/image', methods=['POST'])
def search_image():
    """이미지 검색"""
    if 'file' not in request.files:
        return jsonify({'error': '파일이 없습니다'}), 400

    file = request.files['file']
    filename = secure_filename(file.filename)
    filepath = os.path.join(app.config['UPLOAD_FOLDER'], 'query_' + filename)
    file.save(filepath)

    results = engine.search_by_image(filepath, top_k=10)

    return jsonify({
        'results': results,
        'count': len(results)
    })

if __name__ == '__main__':
    app.run(debug=True, host='0.0.0.0', port=5000)
이제 python app.py로 서버를 실행하고 브라우저에서 http://localhost:5000에 접속하면 돼! 🎉
이미지를 업로드하면 자동으로 인덱싱되고, 텍스트나 이미지로 검색할 수 있어. 실제 서비스에 쓸 수 있는 수준이야! 물론 프로덕션 환경에서는 보안, 에러 처리, 스케일링 등을 더 고려해야 하지만 말이야. 🛡️
🎯 고급 활용: CLIP의 무한한 가능성
기본적인 사용법은 마스터했으니, 이제 더 창의적인 활용법을 알아보자! CLIP은 정말 다양한 분야에 적용할 수 있어. 🌈
🎭 콘텐츠 모더레이션
CLIP을 사용하면 부적절한 콘텐츠를 자동으로 필터링할 수 있어. 특정 카테고리의 이미지를 감지하는 거지!
class ContentModerator:
    def __init__(self):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load("ViT-B/32", device=self.device)

        # 부적절한 콘텐츠 카테고리
        self.inappropriate_categories = [
            "violent content",
            "explicit content",
            "hate symbols",
            "graphic violence"
        ]

        # 적절한 콘텐츠 카테고리
        self.appropriate_categories = [
            "safe for work content",
            "family friendly image",
            "appropriate content",
            "general audience content"
        ]

    def check_image(self, image_path, threshold=0.3):
        """이미지 적절성 검사"""
        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        all_categories = self.inappropriate_categories + self.appropriate_categories
        texts = [f"a photo containing {cat}" for cat in all_categories]
        text_tokens = clip.tokenize(texts).to(self.device)

        with torch.no_grad():
            image_features = self.model.encode_image(image)
            text_features = self.model.encode_text(text_tokens)

            image_features /= image_features.norm(dim=-1, keepdim=True)
            text_features /= text_features.norm(dim=-1, keepdim=True)

            similarity = (100.0 * image_features @ text_features.T).softmax(dim=-1)

        # 부적절한 콘텐츠 점수 계산
        inappropriate_score = similarity[0, :len(self.inappropriate_categories)].sum().item()

        result = {
            'is_safe': inappropriate_score < threshold,
            'inappropriate_score': inappropriate_score,
            'details': {}
        }

        for i, cat in enumerate(all_categories):
            result['details'][cat] = similarity[0, i].item()

        return result

# 사용 예시
moderator = ContentModerator()
result = moderator.check_image("user_upload.jpg")

if result['is_safe']:
    print("✅ 안전한 콘텐츠입니다")
else:
    print(f"⚠️ 부적절한 콘텐츠 가능성: {result['inappropriate_score']:.2%}")
🏷️ 자동 태그 생성
이미지에 자동으로 태그를 달아주는 시스템도 만들 수 있어! 수백 개의 태그 후보 중에서 가장 관련성 높은 태그를 선택하는 거야. 📸
class AutoTagger:
    def __init__(self):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load("ViT-B/32", device=self.device)

        # 태그 후보들 (실제로는 더 많이!)
        self.tag_candidates = [
            # 객체
            "person", "people", "crowd", "dog", "cat", "car", "building",
            "tree", "flower", "food", "phone", "computer", "book",
            # 장소
            "indoor", "outdoor", "city", "nature", "beach", "mountain",
            "park", "street", "room", "office", "restaurant",
            # 활동
            "working", "playing", "eating", "sleeping", "running",
            "reading", "writing", "cooking", "driving",
            # 분위기
            "happy", "sad", "peaceful", "energetic", "romantic",
            "professional", "casual", "formal",
            # 시간/날씨
            "daytime", "nighttime", "sunny", "cloudy", "rainy", "snowy",
            # 스타일
            "colorful", "black and white", "vintage", "modern",
            "minimalist", "artistic", "realistic"
        ]

    def generate_tags(self, image_path, top_k=10, threshold=0.2):
        """이미지에 대한 태그 생성"""
        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        # 배치 처리로 효율성 향상
        batch_size = 50
        all_similarities = []

        for i in range(0, len(self.tag_candidates), batch_size):
            batch_tags = self.tag_candidates[i:i+batch_size]
            texts = [f"a photo of {tag}" for tag in batch_tags]
            text_tokens = clip.tokenize(texts).to(self.device)

            with torch.no_grad():
                image_features = self.model.encode_image(image)
                text_features = self.model.encode_text(text_tokens)

                image_features /= image_features.norm(dim=-1, keepdim=True)
                text_features /= text_features.norm(dim=-1, keepdim=True)

                similarity = (image_features @ text_features.T).squeeze(0)
                all_similarities.append(similarity)

        # 모든 유사도 합치기
        all_similarities = torch.cat(all_similarities)

        # 임계값 이상인 태그만 선택
        valid_indices = (all_similarities > threshold).nonzero(as_tuple=True)[0]

        if len(valid_indices) == 0:
            # 임계값을 만족하는 태그가 없으면 상위 k개 선택
            top_indices = all_similarities.argsort(descending=True)[:top_k]
        else:
            # 임계값 이상 중에서 상위 k개
            valid_similarities = all_similarities[valid_indices]
            sorted_valid = valid_similarities.argsort(descending=True)[:top_k]
            top_indices = valid_indices[sorted_valid]

        tags = []
        for idx in top_indices:
            tags.append({
                'tag': self.tag_candidates[idx],
                'confidence': all_similarities[idx].item()
            })

        return tags

# 사용 예시
tagger = AutoTagger()
tags = tagger.generate_tags("photo.jpg", top_k=15)

print("🏷️ 생성된 태그:")
for tag_info in tags:
    print(f"  #{tag_info['tag']} (신뢰도: {tag_info['confidence']:.3f})")
🎨 이미지 스타일 분석
CLIP으로 이미지의 예술적 스타일이나 분위기를 분석할 수도 있어! 사진작가나 디자이너에게 유용한 기능이지. 🖼️
class StyleAnalyzer:
    def __init__(self):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load("ViT-B/32", device=self.device)

        self.style_dimensions = {
            'color_palette': [
                "vibrant colors", "muted colors", "pastel colors",
                "monochrome", "warm tones", "cool tones"
            ],
            'composition': [
                "symmetrical composition", "asymmetrical composition",
                "rule of thirds", "centered subject", "minimalist composition"
            ],
            'lighting': [
                "natural lighting", "artificial lighting", "dramatic lighting",
                "soft lighting", "harsh shadows", "golden hour lighting"
            ],
            'mood': [
                "cheerful mood", "melancholic mood", "mysterious mood",
                "energetic mood", "calm mood", "romantic mood"
            ],
            'art_style': [
                "realistic style", "abstract style", "impressionist style",
                "modern style", "vintage style", "cinematic style"
            ]
        }

    def analyze(self, image_path):
        """이미지 스타일 종합 분석"""
        image = self.preprocess(Image.open(image_path)).unsqueeze(0).to(self.device)

        analysis_result = {}

        for dimension, options in self.style_dimensions.items():
            texts = [f"a photo with {opt}" for opt in options]
            text_tokens = clip.tokenize(texts).to(self.device)

            with torch.no_grad():
                image_features = self.model.encode_image(image)
                text_features = self.model.encode_text(text_tokens)

                image_features /= image_features.norm(dim=-1, keepdim=True)
                text_features /= text_features.norm(dim=-1, keepdim=True)

                similarity = (100.0 * image_features @ text_features.T).softmax(dim=-1)

            # 가장 높은 점수의 스타일 선택
            top_idx = similarity.argmax().item()

            analysis_result[dimension] = {
                'primary': options[top_idx],
                'confidence': similarity[0, top_idx].item(),
                'all_scores': {opt: similarity[0, i].item()
                              for i, opt in enumerate(options)}
            }

        return analysis_result

# 사용 예시
analyzer = StyleAnalyzer()
analysis = analyzer.analyze("artwork.jpg")

print("🎨 이미지 스타일 분석 결과:\n")
for dimension, result in analysis.items():
    print(f"📊 {dimension.replace('_', ' ').title()}:")
    print(f"   주요 특징: {result['primary']} ({result['confidence']:.1%})")
    print()
🚀 CLIP의 한계와 극복 방법
CLIP이 아무리 강력해도 완벽하진 않아. 한계를 알고 있어야 더 잘 활용할 수 있지! 🎯
⚠️ 주요 한계점들
해결책: OCR(광학 문자 인식)이나 객체 탐지 모델과 결합해서 사용해!
해결책: 추상적 개념을 구체적인 시각적 특징으로 풀어서 설명해. "어두운 조명과 고독한 인물이 있는 사진"처럼!
해결책: 객체 탐지 모델로 먼저 위치를 파악한 후, CLIP으로 객체를 분류하는 파이프라인을 구성해!
해결책: - 특징 벡터를 미리 계산해서 저장 (오프라인 인덱싱) - FAISS 같은 벡터 검색 라이브러리 사용 - 더 작은 모델 사용 (ViT-B/32 대신 RN50)
🔧 성능 개선 팁
| 문제 | 해결 방법 | 효과 |
|---|---|---|
| 느린 검색 속도 | FAISS 벡터 인덱스 사용 | 10~100배 빠름 |
| 메모리 부족 | 배치 크기 줄이기, FP16 사용 | 메모리 50% 절감 |
| 낮은 정확도 | 더 큰 모델 사용 (ViT-L/14) | 정확도 5~10% 향상 |
| 도메인 특화 성능 | 파인튜닝 (Fine-tuning) | 특정 도메인 20~30% 향상 |
🌐 FAISS와 결합: 대규모 검색 시스템
수백만 개의 이미지를 검색하려면 FAISS(Facebook AI Similarity Search)를 사용해야 해! 벡터 검색에 최적화된 라이브러리야. 🚄
import faiss
import numpy as np

class ScalableImageSearch:
    def __init__(self, model_name="ViT-B/32", dimension=512):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load(model_name, device=self.device)
        self.dimension = dimension

        # FAISS 인덱스 초기화 (코사인 유사도용)
        self.index = faiss.IndexFlatIP(dimension)  # Inner Product (정규화된 벡터면 코사인)
        self.image_paths = []

    def add_images_batch(self, image_paths, batch_size=32):
        """대량의 이미지를 배치로 추가"""
        print(f"📥 {len(image_paths)}개 이미지 인덱싱 시작...")

        for i in range(0, len(image_paths), batch_size):
            batch_paths = image_paths[i:i+batch_size]

            # 배치 이미지 로드
            images = []
            valid_paths = []

            for path in batch_paths:
                try:
                    image = self.preprocess(Image.open(path))
                    images.append(image)
                    valid_paths.append(path)
                except Exception as e:
                    print(f"⚠️ 이미지 로드 실패: {path}")
                    continue

            if not images:
                continue

            # 배치 인코딩
            batch_tensor = torch.stack(images).to(self.device)

            with torch.no_grad():
                features = self.model.encode_image(batch_tensor)
                features /= features.norm(dim=-1, keepdim=True)

            # FAISS에 추가 (numpy 배열로 변환)
            features_np = features.cpu().numpy().astype('float32')
            self.index.add(features_np)
            self.image_paths.extend(valid_paths)

            if (i + batch_size) % 1000 == 0:
                print(f"  진행: {i + batch_size}/{len(image_paths)}")

        print(f"✅ 인덱싱 완료! 총 {len(self.image_paths)}개 이미지")

    def search(self, query, top_k=10, query_type='text'):
        """검색 (텍스트 또는 이미지)"""
        if query_type == 'text':
            text = clip.tokenize([query]).to(self.device)
            with torch.no_grad():
                query_features = self.model.encode_text(text)
                query_features /= query_features.norm(dim=-1, keepdim=True)
        else:  # image
            image = self.preprocess(Image.open(query)).unsqueeze(0).to(self.device)
            with torch.no_grad():
                query_features = self.model.encode_image(image)
                query_features /= query_features.norm(dim=-1, keepdim=True)

        # FAISS 검색
        query_np = query_features.cpu().numpy().astype('float32')
        distances, indices = self.index.search(query_np, top_k)

        results = []
        for i, idx in enumerate(indices[0]):
            if idx < len(self.image_paths):  # 유효한 인덱스인지 확인
                results.append({
                    'path': self.image_paths[idx],
                    'score': float(distances[0][i])
                })

        return results

    def save_index(self, filepath):
        """인덱스 저장"""
        faiss.write_index(self.index, f"{filepath}.faiss")
        with open(f"{filepath}.paths", 'wb') as f:
            pickle.dump(self.image_paths, f)
        print(f"💾 인덱스 저장 완료: {filepath}")

    def load_index(self, filepath):
        """인덱스 로드"""
        self.index = faiss.read_index(f"{filepath}.faiss")
        with open(f"{filepath}.paths", 'rb') as f:
            self.image_paths = pickle.load(f)
        print(f"📂 인덱스 로드 완료: {len(self.image_paths)}개 이미지")

# 사용 예시
search_engine = ScalableImageSearch()

# 대량 이미지 인덱싱
import glob
all_images = glob.glob("./image_dataset/**/*.jpg", recursive=True)
search_engine.add_images_batch(all_images, batch_size=64)

# 인덱스 저장
search_engine.save_index("./my_image_index")

# 나중에 로드
# search_engine.load_index("./my_image_index")

# 검색
results = search_engine.search("a beautiful sunset", top_k=20)
for i, result in enumerate(results, 1):
    print(f"{i}. {result['path']} (유사도: {result['score']:.4f})")
FAISS를 사용하면 백만 개 이미지에서도 밀리초 단위로 검색할 수 있어! 🚀 실제 서비스 수준의 성능이지. 재능넷 같은 플랫폼에서 사용자들이 업로드한 수많은 포트폴리오 이미지를 검색하는 데도 활용할 수 있을 거야!
🎓 파인튜닝: 나만의 도메인에 최적화하기
CLIP은 범용적으로 훌륭하지만, 특정 도메인(의료, 패션, 부동산 등)에서는 파인튜닝하면 훨씬 좋은 성능을 낼 수 있어! 🎯
📚 파인튜닝 준비
파인튜닝하려면 도메인 특화 데이터셋이 필요해. 이미지-텍스트 쌍으로 구성된 데이터야. 예를 들어, 패션 도메인이라면:
- 텍스트: "빨간색 플레어 원피스, 무릎 길이, 반팔, 여름용"
- 이미지: shoes_045.jpg
- 텍스트: "검은색 가죽 앵클부츠, 청키힐, 지퍼 디테일"
최소 수천 개, 이상적으로는 수만 개의 쌍이 필요해!
import torch
import torch.nn as nn
from torch.utils.data import Dataset, DataLoader
import clip

class CustomImageTextDataset(Dataset):
    def __init__(self, image_paths, captions, preprocess):
        self.image_paths = image_paths
        self.captions = captions
        self.preprocess = preprocess

    def __len__(self):
        return len(self.image_paths)

    def __getitem__(self, idx):
        image = self.preprocess(Image.open(self.image_paths[idx]))
        caption = self.captions[idx]
        return image, caption

def finetune_clip(model, train_loader, epochs=10, lr=1e-6, device="cuda"):
    """CLIP 파인튜닝"""
    # 옵티마이저 설정 (학습률을 매우 낮게!)
    optimizer = torch.optim.Adam(model.parameters(), lr=lr, betas=(0.9, 0.98), eps=1e-6)

    # 학습률 스케줄러
    scheduler = torch.optim.lr_scheduler.CosineAnnealingLR(optimizer, T_max=epochs)

    model.train()

    for epoch in range(epochs):
        total_loss = 0

        for batch_idx, (images, texts) in enumerate(train_loader):
            images = images.to(device)
            texts = clip.tokenize(texts, truncate=True).to(device)

            # Forward pass
            logits_per_image, logits_per_text = model(images, texts)

            # Contrastive loss
            batch_size = images.shape[0]
            labels = torch.arange(batch_size).to(device)

            loss_i = nn.CrossEntropyLoss()(logits_per_image, labels)
            loss_t = nn.CrossEntropyLoss()(logits_per_text, labels)
            loss = (loss_i + loss_t) / 2

            # Backward pass
            optimizer.zero_grad()
            loss.backward()

            # 그래디언트 클리핑 (안정성을 위해)
            torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=1.0)

            optimizer.step()

            total_loss += loss.item()

            if batch_idx % 100 == 0:
                print(f"Epoch {epoch+1}/{epochs}, Batch {batch_idx}, Loss: {loss.item():.4f}")

        scheduler.step()
        avg_loss = total_loss / len(train_loader)
        print(f"Epoch {epoch+1} 완료, 평균 Loss: {avg_loss:.4f}")

        # 체크포인트 저장
        torch.save({
            'epoch': epoch,
            'model_state_dict': model.state_dict(),
            'optimizer_state_dict': optimizer.state_dict(),
            'loss': avg_loss,
        }, f'clip_finetuned_epoch_{epoch+1}.pt')

# 사용 예시
device = "cuda" if torch.cuda.is_available() else "cpu"
model, preprocess = clip.load("ViT-B/32", device=device)

# 데이터 준비
image_paths = ["path/to/image1.jpg", "path/to/image2.jpg", ...]
captions = ["caption for image 1", "caption for image 2", ...]

dataset = CustomImageTextDataset(image_paths, captions, preprocess)
train_loader = DataLoader(dataset, batch_size=32, shuffle=True, num_workers=4)

# 파인튜닝 시작
finetune_clip(model, train_loader, epochs=10, lr=1e-6, device=device)
2. 데이터 증강: 이미지 회전, 크롭, 색상 조정 등으로 데이터를 늘려
3. 점진적 학습: 처음엔 마지막 레이어만, 나중에 전체 모델을 학습
4. 검증 세트: 과적합을 막기 위해 검증 세트로 성능을 모니터링해!
🌟 실전 활용 사례: 현업에서는 이렇게 써요
이론과 코드는 충분히 봤으니, 이제 실제로 어떻게 활용되는지 알아보자! 🏢
🛍️ 전자상거래: 비주얼 검색
온라인 쇼핑몰에서 "이 옷과 비슷한 상품 찾기" 기능, 본 적 있지? 그게 바로 CLIP 같은 기술이야! 사용자가 마음에 드는 상품 이미지를 업로드하면, 비슷한 스타일의 상품을 추천해주는 거지. 👗
실제 구현 포인트:
- 전체 상품 카탈로그를 미리 인덱싱
- 사용자 업로드 이미지를 실시간으로 인코딩
- FAISS로 빠른 유사 상품 검색
- 가격대, 브랜드 등 필터와 결합
📱 소셜 미디어: 콘텐츠 추천
인스타그램이나 핀터레스트 같은 플랫폼에서 "당신이 좋아할 만한 게시물"을 추천할 때도 비슷한 기술을 써. 사용자가 좋아요를 누른 이미지들의 패턴을 학습해서, 비슷한 스타일의 콘텐츠를 찾아주는 거야! 📸
재능넷 같은 플랫폼에서도 활용할 수 있어! 사용자가 관심 있어 하는 포트폴리오 스타일을 분석해서, 비슷한 재능을 가진 다른 크리에이터를 추천해주는 거지. 🎨
🏥 의료: 의료 이미지 검색
의사들이 비슷한 증례를 찾을 때도 CLIP을 활용할 수 있어. "폐렴 패턴이 있는 X-ray"처럼 자연어로 검색하면, 관련 의료 이미지를 찾아주는 거야. 물론 의료 도메인에 파인튜닝된 모델을 써야 하지만! 🏥
🎬 미디어: 비디오 콘텐츠 분석
비디오를 프레임별로 분석해서 특정 장면을 찾을 수 있어. "해변에서 일몰을 보는 장면"을 검색하면, 수시간짜리 영상에서 해당 장면만 쏙 찾아내는 거지! 🎥
import cv2

class VideoSearchEngine:
    def __init__(self):
        self.device = "cuda" if torch.cuda.is_available() else "cpu"
        self.model, self.preprocess = clip.load("ViT-B/32", device=self.device)

    def search_in_video(self, video_path, query, threshold=0.25, sample_rate=30):
        """비디오에서 쿼리와 매칭되는 장면 찾기"""
        cap = cv2.VideoCapture(video_path)
        fps = cap.get(cv2.CAP_PROP_FPS)

        text = clip.tokenize([query]).to(self.device)
        with torch.no_grad():
            text_features = self.model.encode_text(text)
            text_features /= text_features.norm(dim=-1, keepdim=True)

        matching_frames = []
        frame_count = 0

        while cap.isOpened():
            ret, frame = cap.read()
            if not ret:
                break

            # 샘플링 (모든 프레임을 처리하면 너무 느림)
            if frame_count % sample_rate == 0:
                # OpenCV BGR을 RGB로 변환
                frame_rgb = cv2.cvtColor(frame, cv2.COLOR_BGR2RGB)
                pil_image = Image.fromarray(frame_rgb)

                image = self.preprocess(pil_image).unsqueeze(0).to(self.device)

                with torch.no_grad():
                    image_features = self.model.encode_image(image)
                    image_features /= image_features.norm(dim=-1, keepdim=True)

                    similarity = (image_features @ text_features.T).item()

                if similarity > threshold:
                    timestamp = frame_count / fps
                    matching_frames.append({
                        'frame': frame_count,
                        'timestamp': timestamp,
                        'similarity': similarity
                    })
                    print(f"✅ 매칭 발견: {timestamp:.2f}초 (유사도: {similarity:.3f})")

            frame_count += 1

        cap.release()
        return matching_frames

# 사용 예시
video_search = VideoSearchEngine()
results = video_search.search_in_video(
    "movie.mp4",
    "a person running on the beach",
    threshold=0.3,
    sample_rate=15  # 15프레임마다 샘플링
)

print(f"\n🎬 총 {len(results)}개 장면 발견!")
🔮 CLIP의 미래와 발전 방향
CLIP은 계속 진화하고 있어! 최신 트렌드와 미래 방향을 알아보자. 🚀
🆕 CLIP의 후속 모델들
🎯 향후 발전 방향
1. 더 큰 규모
더 많은 데이터, 더 큰 모델로 성능이 계속 향상되고 있어. CLIP의 학습 데이터는 4억 개였지만, 최신 모델들은 수십억 개를 사용해! 📈
2. 비디오 이해
정적 이미지뿐만 아니라 비디오의 시간적 흐름까지 이해하는 모델들이 나오고 있어. 🎬
3. 3D 이해
2D 이미지를 넘어 3D 공간을 이해하는 모델들도 연구 중이야. AR/VR 분야에서 활용될 거야! 🥽
4. 효율성 개선
모바일 기기에서도 돌아갈 수 있는 경량화 모델들이 개발되고 있어. 엣지 컴퓨팅의 시대! 📱
💡 실전 프로젝트 아이디어
이제 배운 걸 활용해서 뭘 만들 수 있을까? 재미있는 프로젝트 아이디어들을 소개할게! 🎨
핵심 기능:
- 자동 태그 생성
- 자연어 검색
- 비슷한 사진 그룹핑
- 추억 자동 생성
핵심 기능:
- 의류 자동 분류 (상의, 하의, 신발 등)
- 색상/스타일 분석
- 날씨/상황별 코디 추천
- 비슷한 스타일 쇼핑 추천
핵심 기능:
- 스타일별 이미지 검색
- 비슷한 가구 찾기
- 색상 팔레트 추출
- 쇼핑몰 연동
핵심 기능:
- 과목/주제별 자동 분류
- 내용 기반 검색
- 관련 자료 추천
- 복습 스케줄 생성
🎓 학습 리소스와 커뮤니티
더 깊이 공부하고 싶다면? 유용한 리소스들을 모아봤어! 📚
📖 공식 문서 및 논문
2. OpenAI CLIP GitHub: 공식 코드와 모델 다운로드
3. Hugging Face Transformers 문서: CLIP 사용 가이드
4. OpenCLIP: 커뮤니티 버전 CLIP
💻 실습 플랫폼
Google Colab: 무료 GPU로 CLIP 실습하기 좋아! 🆓
Kaggle Notebooks: 다양한 CLIP 활용 예제들
Hugging Face Spaces: 웹에서 바로 테스트할 수 있는 데모들
🌐 커뮤니티
Reddit r/MachineLearning: 최신 연구 동향
Papers with Code: CLIP 관련 논문과 코드
Discord AI 커뮤니티들: 실시간 질문과 답변
재능넷 AI/머신러닝 카테고리: 한국어로 소통하며 배우기! 🇰🇷
🎬 마무리하며
와, 정말 긴 여정이었지? 🎉 우리는 CLIP의 기본 개념부터 시작해서, 실전 구현, 최적화, 고급 활용까지 모든 걸 다뤘어!
CLIP은 정말 강력한 도구야. 이미지와 텍스트를 자유롭게 연결할 수 있다는 건, 무궁무진한 가능성을 의미해. 검색 엔진, 추천 시스템, 콘텐츠 모더레이션, 크리에이티브 툴... 생각할 수 있는 거의 모든 분야에 적용할 수 있지! 🌈
중요한 건 직접 해보는 거야! 이 글에서 소개한 코드들을 복사-붙여넣기만 하지 말고, 직접 수정해보고 실험해봐. 실패도 해보고, 에러도 만나보고, 그러면서 진짜 실력이 늘어나는 거야. 💪
재능넷 같은 플랫폼에서 여러분의 CLIP 프로젝트를 공유하고, 다른 사람들과 협업하는 것도 좋은 방법이야. 혼자 하는 것보다 함께 하면 훨씬 빨리 성장할 수 있거든! 🤝
AI 기술은 계속 발전하고 있어. CLIP도 마찬가지야. 오늘 배운 내용이 내일이면 구식이 될 수도 있지. 하지만 기본 원리와 개념은 변하지 않아. 그걸 탄탄히 이해하고 있으면, 새로운 기술이 나와도 금방 따라잡을 수 있어! 🚀
자, 이제 여러분 차례야! 키보드를 두드리고, 코드를 작성하고, 멋진 프로젝트를 만들어봐. 그리고 막히는 게 있으면 언제든 커뮤니티에 물어봐. 우리 모두 함께 배우고 성장하는 거니까! 😊
행운을 빌어! 그리고 즐거운 코딩 되길! 🎨✨

댓글 작성
이 글에 대한 여러분의 생각을 들려주세요
로그인이 필요합니다
댓글을 작성하려면 먼저 로그인해주세요.
댓글 0
지식인의 숲 - 지적 재산권 보호 고지
지적 재산권 보호 고지
- 저작권 및 소유권: 본 컨텐츠는 재능넷의 독점 AI 기술로 생성되었으며, 대한민국 저작권법 및 국제 저작권 협약에 의해 보호됩니다.
- AI 생성 컨텐츠의 법적 지위: 본 AI 생성 컨텐츠는 재능넷의 지적 창작물로 인정되며, 관련 법규에 따라 저작권 보호를 받습니다.
- 사용 제한: 재능넷의 명시적 서면 동의 없이 본 컨텐츠를 복제, 수정, 배포, 또는 상업적으로 활용하는 행위는 엄격히 금지됩니다.
- 데이터 수집 금지: 본 컨텐츠에 대한 무단 스크래핑, 크롤링, 및 자동화된 데이터 수집은 법적 제재의 대상이 됩니다.
- AI 학습 제한: 재능넷의 AI 생성 컨텐츠를 타 AI 모델 학습에 무단 사용하는 행위는 금지되며, 이는 지적 재산권 침해로 간주됩니다.
아직 댓글이 없습니다.